Custom collection · End-to-end as a service
Custom data collection as a service, end-to-end.
- Reach
- 150+ countries
- Stages owned
- 7 of 7
- Your work
- Approve spec + pilot
- License
- Buyer-owned
Validated hours delivered
how we count ›
Hours that passed sync + QA and shipped to a buyer. Recaptured and rejected hours excluded.
Median cross-stream sync error
how we count ›
Median absolute timestamp offset between head camera and every other stream, over 12,480 measured frames.
Documented consent
how we count ›
Every participant signs a written commercial release before capture. Bystanders are de-identified or the clip is discarded.
Median time to first delivery
how we count ›
Signed spec to first validated batch in your hands. Measured across Spec Pilot engagements in environments where coverage is already deep — thin scenarios take longer to staff.
What it is
Data collection you buy as an outcome, not a toolset.
Most teams that need custom AI data end up acting as a general contractor: a crowd here, a labelling shop there, a QA script to referee. Custom collection as a service replaces all of it with one accountable owner.
What we run
- 01Scoping & specWe turn your model failure into a written spec with accept and reject criteria. You approve it.
- 02Recruiting & consentContributors sourced, paid, and signed — releases stored per item, per jurisdiction.
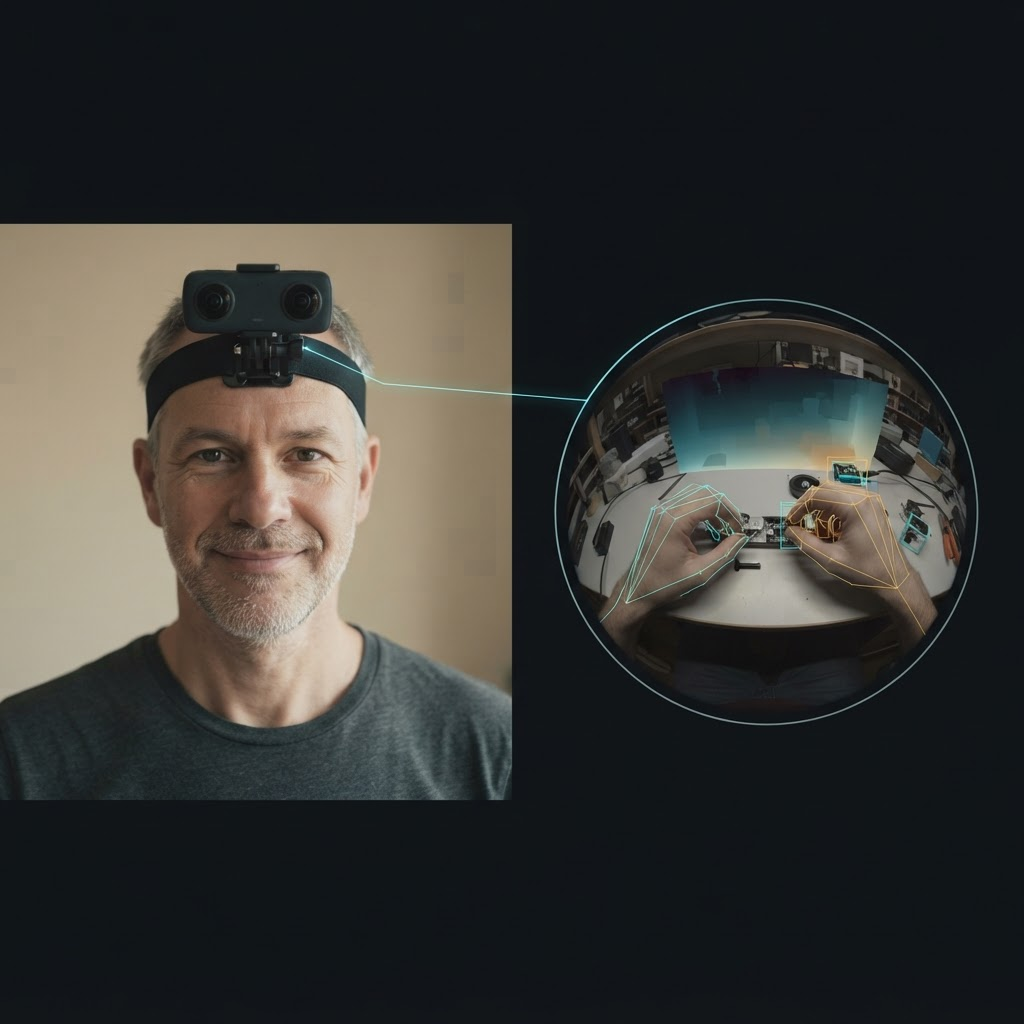
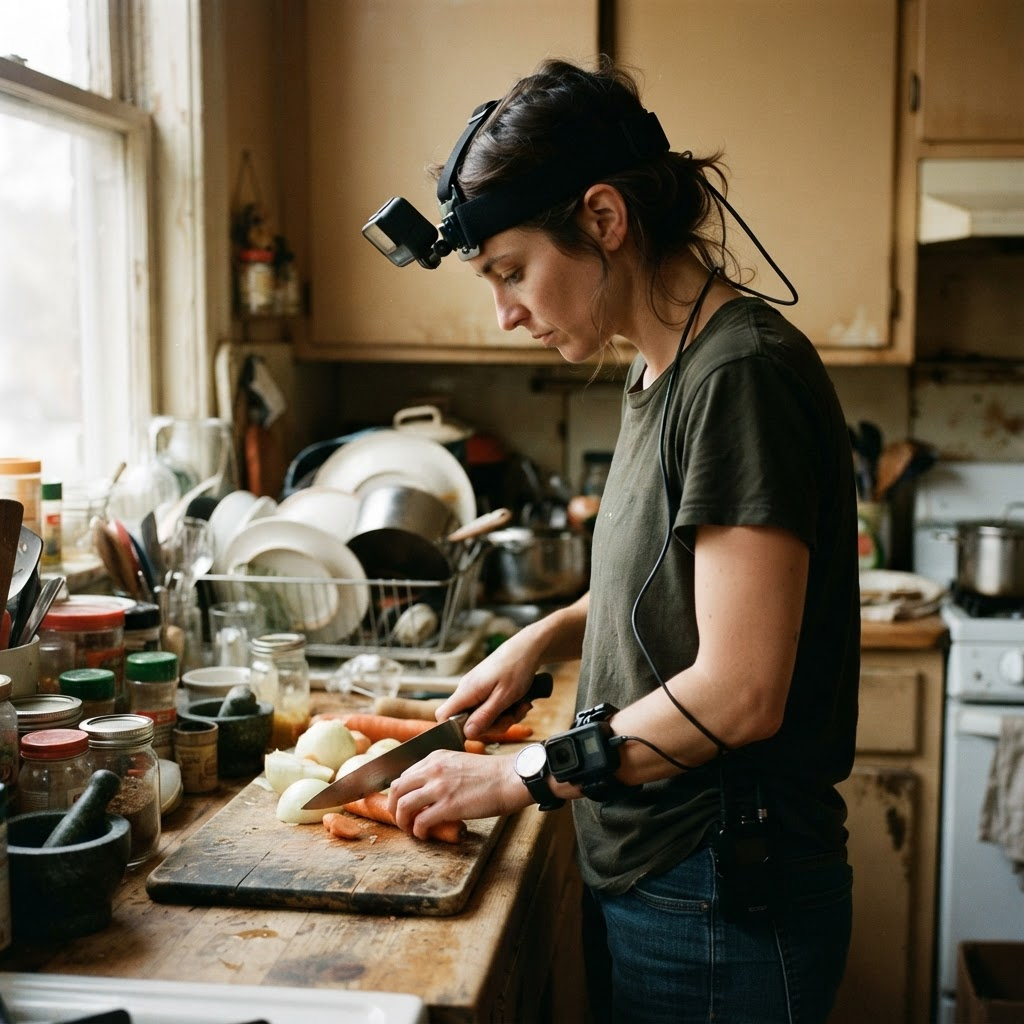
- 03Hardware & capturePhone mounts, 360 head-mounts, or the full synchronized rig, shipped and briefed by us.
- 04AnnotationHand pose, depth, segmentation, action labels, transcripts — whatever the spec names.
- 05AnonymizationFaces, plates, and screens detected, boxed, and blurred before anything leaves QA.
- 06QA & rejectsEvery take scored against the spec. Failures are discarded, logged, and replaced, not downgraded.
- 07Delivery & licenseYour format, your bucket, a data card, and a perpetual buyer-owned commercial license.
What you do
- Describe the gapWhere the model fails — a task, an environment, a population, a language.
- Approve the specOne sign-off on what counts as a good sample before anyone is briefed.
- Review the pilotA small first batch to confirm the data trains the way you expect.
- Receive batchesScheduled drops at the agreed cadence until the target volume is met.
Four touchpoints. Everything between them is ours.
Global mobilization
5,000 videos. 16 countries. Under three weeks.
When a lab needed a rare manipulation skill covered fast and worldwide, we stood up a vetted operator network across four continents and delivered a full spec — not a teaser — in nineteen days. Off-the-shelf corpora take quarters to license; a bespoke shoot on this footprint is the kind of international turnaround most vendors quote in months.
Capture velocity
cumulative to 5,000
Illustrative engagement, anonymised at the buyer's request. Only sync- and QA-passed videos counted.
- 5,000videos
- Validated & delivered
- 19days
- Signed spec to final batch
- 16countries
- Live capture, 4 continents
- 260/day
- Peak validated throughput
International footprint
- United States
- Canada
- Mexico
- Brazil
- United Kingdom
- Germany
- Poland
- Spain
- Nigeria
- Kenya
- India
- Philippines
- Vietnam
- Japan
- South Korea
- Australia
Custom collection
End-to-end custom data collection for AI.
When the training data you need does not exist yet, we build it — from the first problem statement to an owned, licensed dataset. One team owns spec, sourcing, capture, annotation, QA, and delivery, so you brief once instead of stitching together crowds, tools, and reviewers.
- 01Discovery
- 02Specification
- 03Sourcing & staffing
- 04Capture
- 05Annotation & structuring
- 06QA & anonymization
- 07Licensed delivery
Explore custom data collection for AI training by model type, or run the same pipeline worldwide with custom collection across 150+ countries. Need it fast? Try on-demand data collection, fast data collection, stereoscopic video, embodied AI data collection, or pretraining data collection for robot foundation models.
How we capture
One clock domain, or it isn't a dataset.
Ten streams recorded on separate sensors are ten separate videos until something forces them onto the same timebase. We hardware-trigger every sensor from a single PTP grandmaster, and we publish the resulting error distribution.
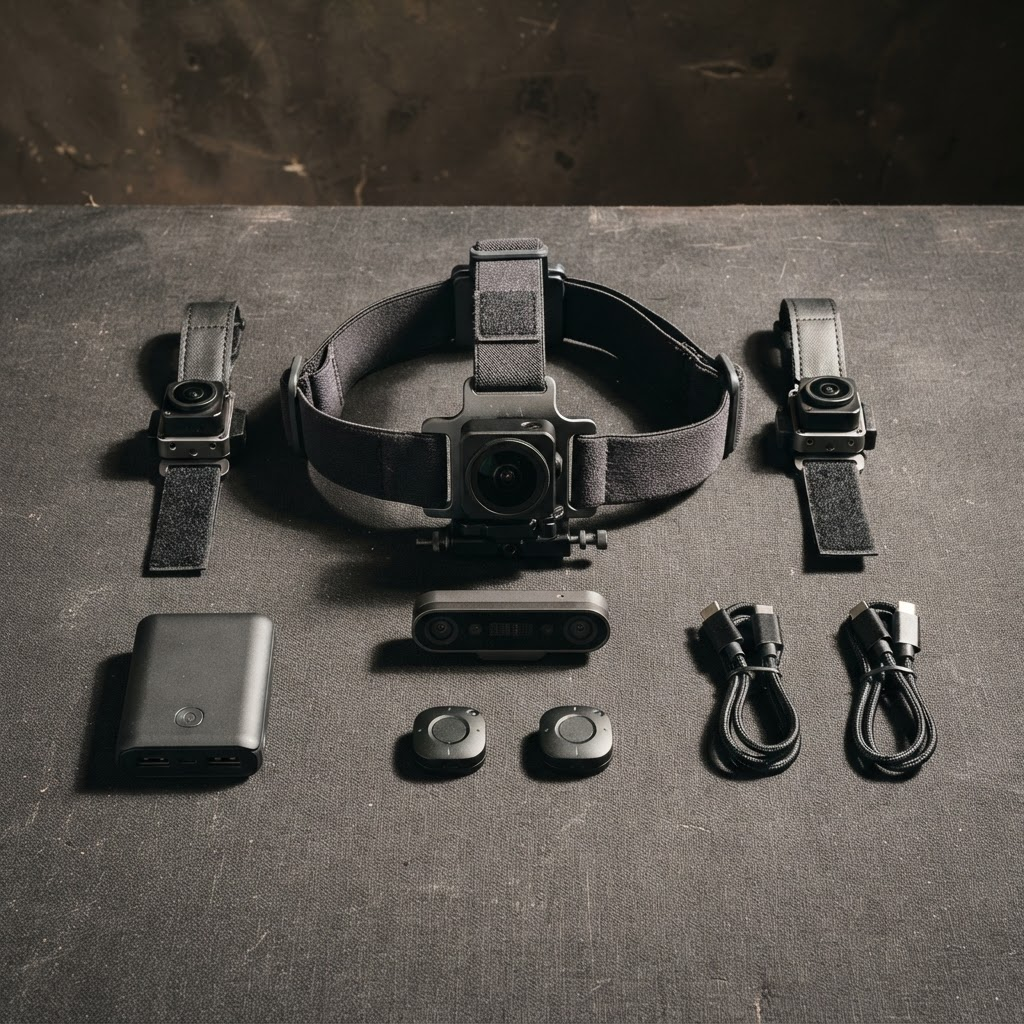
| Head camera | Sony IMX585 global shutter · 120° M12 | Carbon headband, 42 g |
| Wrist cameras | IMX290 ×2 · 100° M12 | Velcro cuff, rigid plate |
| Depth | Intel RealSense D435if | Forehead, 18 mm below head cam |
| IMU | Bosch BMI088 ×3 · 200 Hz | Head, both wrists |
| Clock | PTP grandmaster + hardware trigger | Belt pack, 190 g |
| Storage | 2 TB NVMe · 6 h continuous | Belt pack |
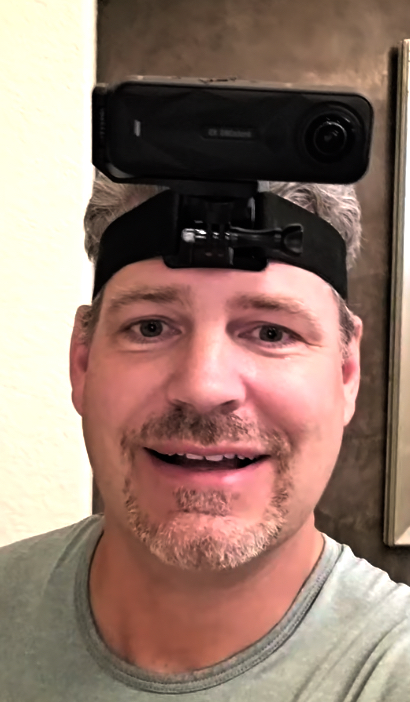
Two capture tiers
The bill of materials above describes our instrumented rig — the tier that carries wrist cameras, depth and a hardware-triggered clock, and the only tier the sync figure below applies to. FIG 2 shows the other tier: a contributor-worn 360 camera on a head strap. It gives up depth, wrist views and sub-millisecond sync, and in exchange it goes anywhere a person is willing to wear it, which is how coverage reaches every country on the map.
The three sample clips published on this site come from the 360 tier, which is why each one is a circular fisheye image circle rather than the rectilinear frame the head camera in the table produces. Read every multi-stream claim on this page — extrinsics, depth validity, the 2.0 ms ceiling — as scoped to the instrumented rig. Single-stream RGB from the 360 tier is labelled as such in the episode metadata, so you can filter on tier rather than infer it.
Rig architecture
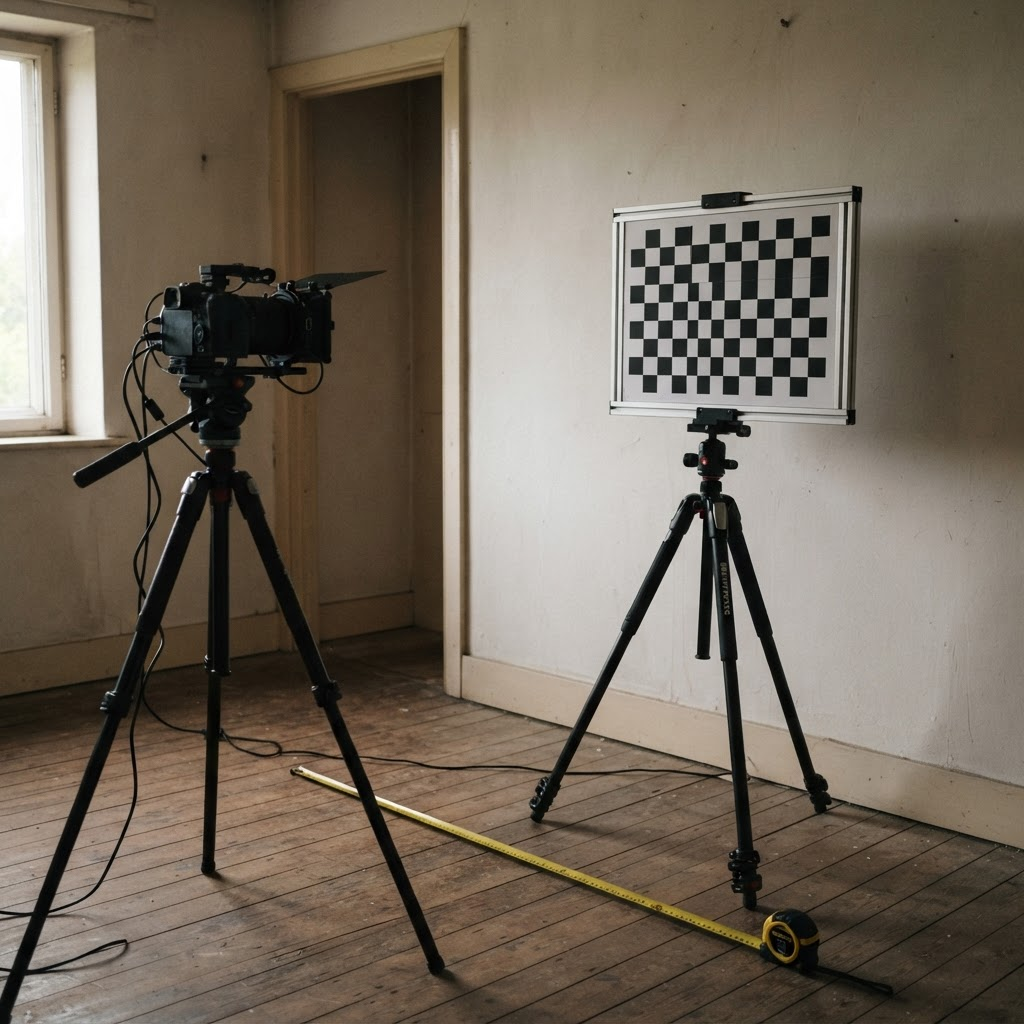
Four device groups, one trigger, one episode file. The clock node is the only part of this diagram that is hard.
Measured sync error
Absolute timestamp offset between the head camera and every other stream, sampled across randomly selected frames from shipped episodes.
Method, tooling and the raw CSV behind this plot are in the sync measurement guide. Nobody else in this category publishes this number, which is exactly why we do.
What ships with every clip
Ten streams, one clock, one episode file.
Not an à la carte menu. Every validated hour we deliver carries the whole stack, in the schema below, whether you asked for depth or not.
| Stream | Spec | Detail |
|---|---|---|
| Head camera | 3840 × 2160 · 60 fps | Global-shutter, 120° HFOV, rolling-shutter-free, H.265 + lossless keyframes |
| Wrist cameras × 2 | 1920 × 1080 · 60 fps | Left + right, 100° HFOV, rigid mount, extrinsics re-solved per session |
| Depth | 848 × 480 · 30 fps | Active stereo, 0.3–4 m range, metric millimetres, per-frame confidence map |
| IMU | 200 Hz · 6-DoF | Accel + gyro, bias-calibrated, hardware-timestamped on the same clock domain |
| Hand pose | 21 keypoints × 2 hands | 3D metric, per-joint visibility flag, contact events on grasp and release |
| Body pose | 24 joints | 3D, root-relative and world-frame, torso and forearm chains resolved |
| Segmentation | Instance masks | Manipulated objects + target surfaces, tracked IDs across the episode |
| Action segments | Verb + noun taxonomy | 97 verbs, 512 nouns, start/end to the frame, human-reviewed |
| Formats | RLDS · LeRobot · WebDataset | Also HDF5, zarr, and .rrd for Rerun. Converters shipped as source. |
| License | Commercial · buyer-owned | Perpetual, irrevocable, model-weights-clean. Exclusivity available. |
Colour dots map to the modality legend used in every chart on this site. Full field-level schema in the episode schema docs.
Coverage — and what we don't have
Everyone publishes a bigger number. We publish the histogram, including the gaps.
If your task lives in a thin column, that is a spec conversation, not a no. Thin cells are where we are actively accepting specs, and where a pilot buys you exclusivity on the capture.
Service vs. do-it-yourself
Where assembled pipelines break, and why a service does not.
The failures in AI data live in the handoffs. Owning every stage is what keeps the spec, the consent chain, and the reject bar intact from the first brief to the last delivery.
| Assemble it yourself | Firsthand as a service | |
|---|---|---|
| Vendors to manage | Crowd platform + labelling shop + QA tool | One team, one contract |
| Who owns the spec | You, re-explained at every handoff | Us, enforced at every stage |
| Consent chain | Scattered across platforms | Per-item releases, one record |
| Privacy | Separate redaction tool, if any | Anonymization built into QA |
| Bad data | Discovered after delivery | Rejected, logged, and replaced |
| Rights | Varies by platform terms | Perpetual, buyer-owned license |
Weighing a service against buying a finished dataset instead? Compare custom collection with off-the-shelf datasets.
Provenance and consent
The license is a product surface, not a footnote.
Your legal team will read this section before your research team reads the specs. So here is the actual release language, the actual pay, and the actual de-identification pipeline.
Participant release — verbatim
What contributors are paid
- Base session rate
- $38 / hour
- Includes
- Setup, calibration, breaks, travel over 20 min
- Thin-coverage premium
- +$12 / hour (clinical, construction, agriculture)
- Payment terms
- Net 7, no per-task bounty, no rejection clawback
Published because a per-task bounty produces rushed, unusable footage. Collector standards.
De-identification pipeline
- Faces
- Bystander faces detected and blurred; participant faces mostly out of frame by rig geometry
- Plates
- Licence plates and street numbers blurred on all outdoor and automotive footage
- Audio
- Speech scrubbed of names, addresses and card numbers; ambient audio retained
- Screens
- Visible phone and monitor content masked unless it is the manipulated object
- Bystanders
- If a person cannot be de-identified, the clip is discarded rather than shipped
Jurisdictions of capture
- United States
- Canada
- United Kingdom
- Germany
- Netherlands
- Poland
- Portugal
- Japan
- South Korea
- Singapore
- Mexico
- Brazil
- GDPR ART. 6(1)(a)
- CCPA / CPRA
- UK GDPR
- APPI (JP)
- PIPEDA (CA)
- SOC 2 TYPE II — IN AUDIT
Anonymization as a service
The de-identification pass we run on every dataset, open to your footage.
Computer vision detects every face, plate, and legible screen, draws a bounding box, and blurs it irreversibly into the delivered pixels — confirmed by a human before anything ships. Send hours or millions of frames; run it by hand or straight from the batch API.
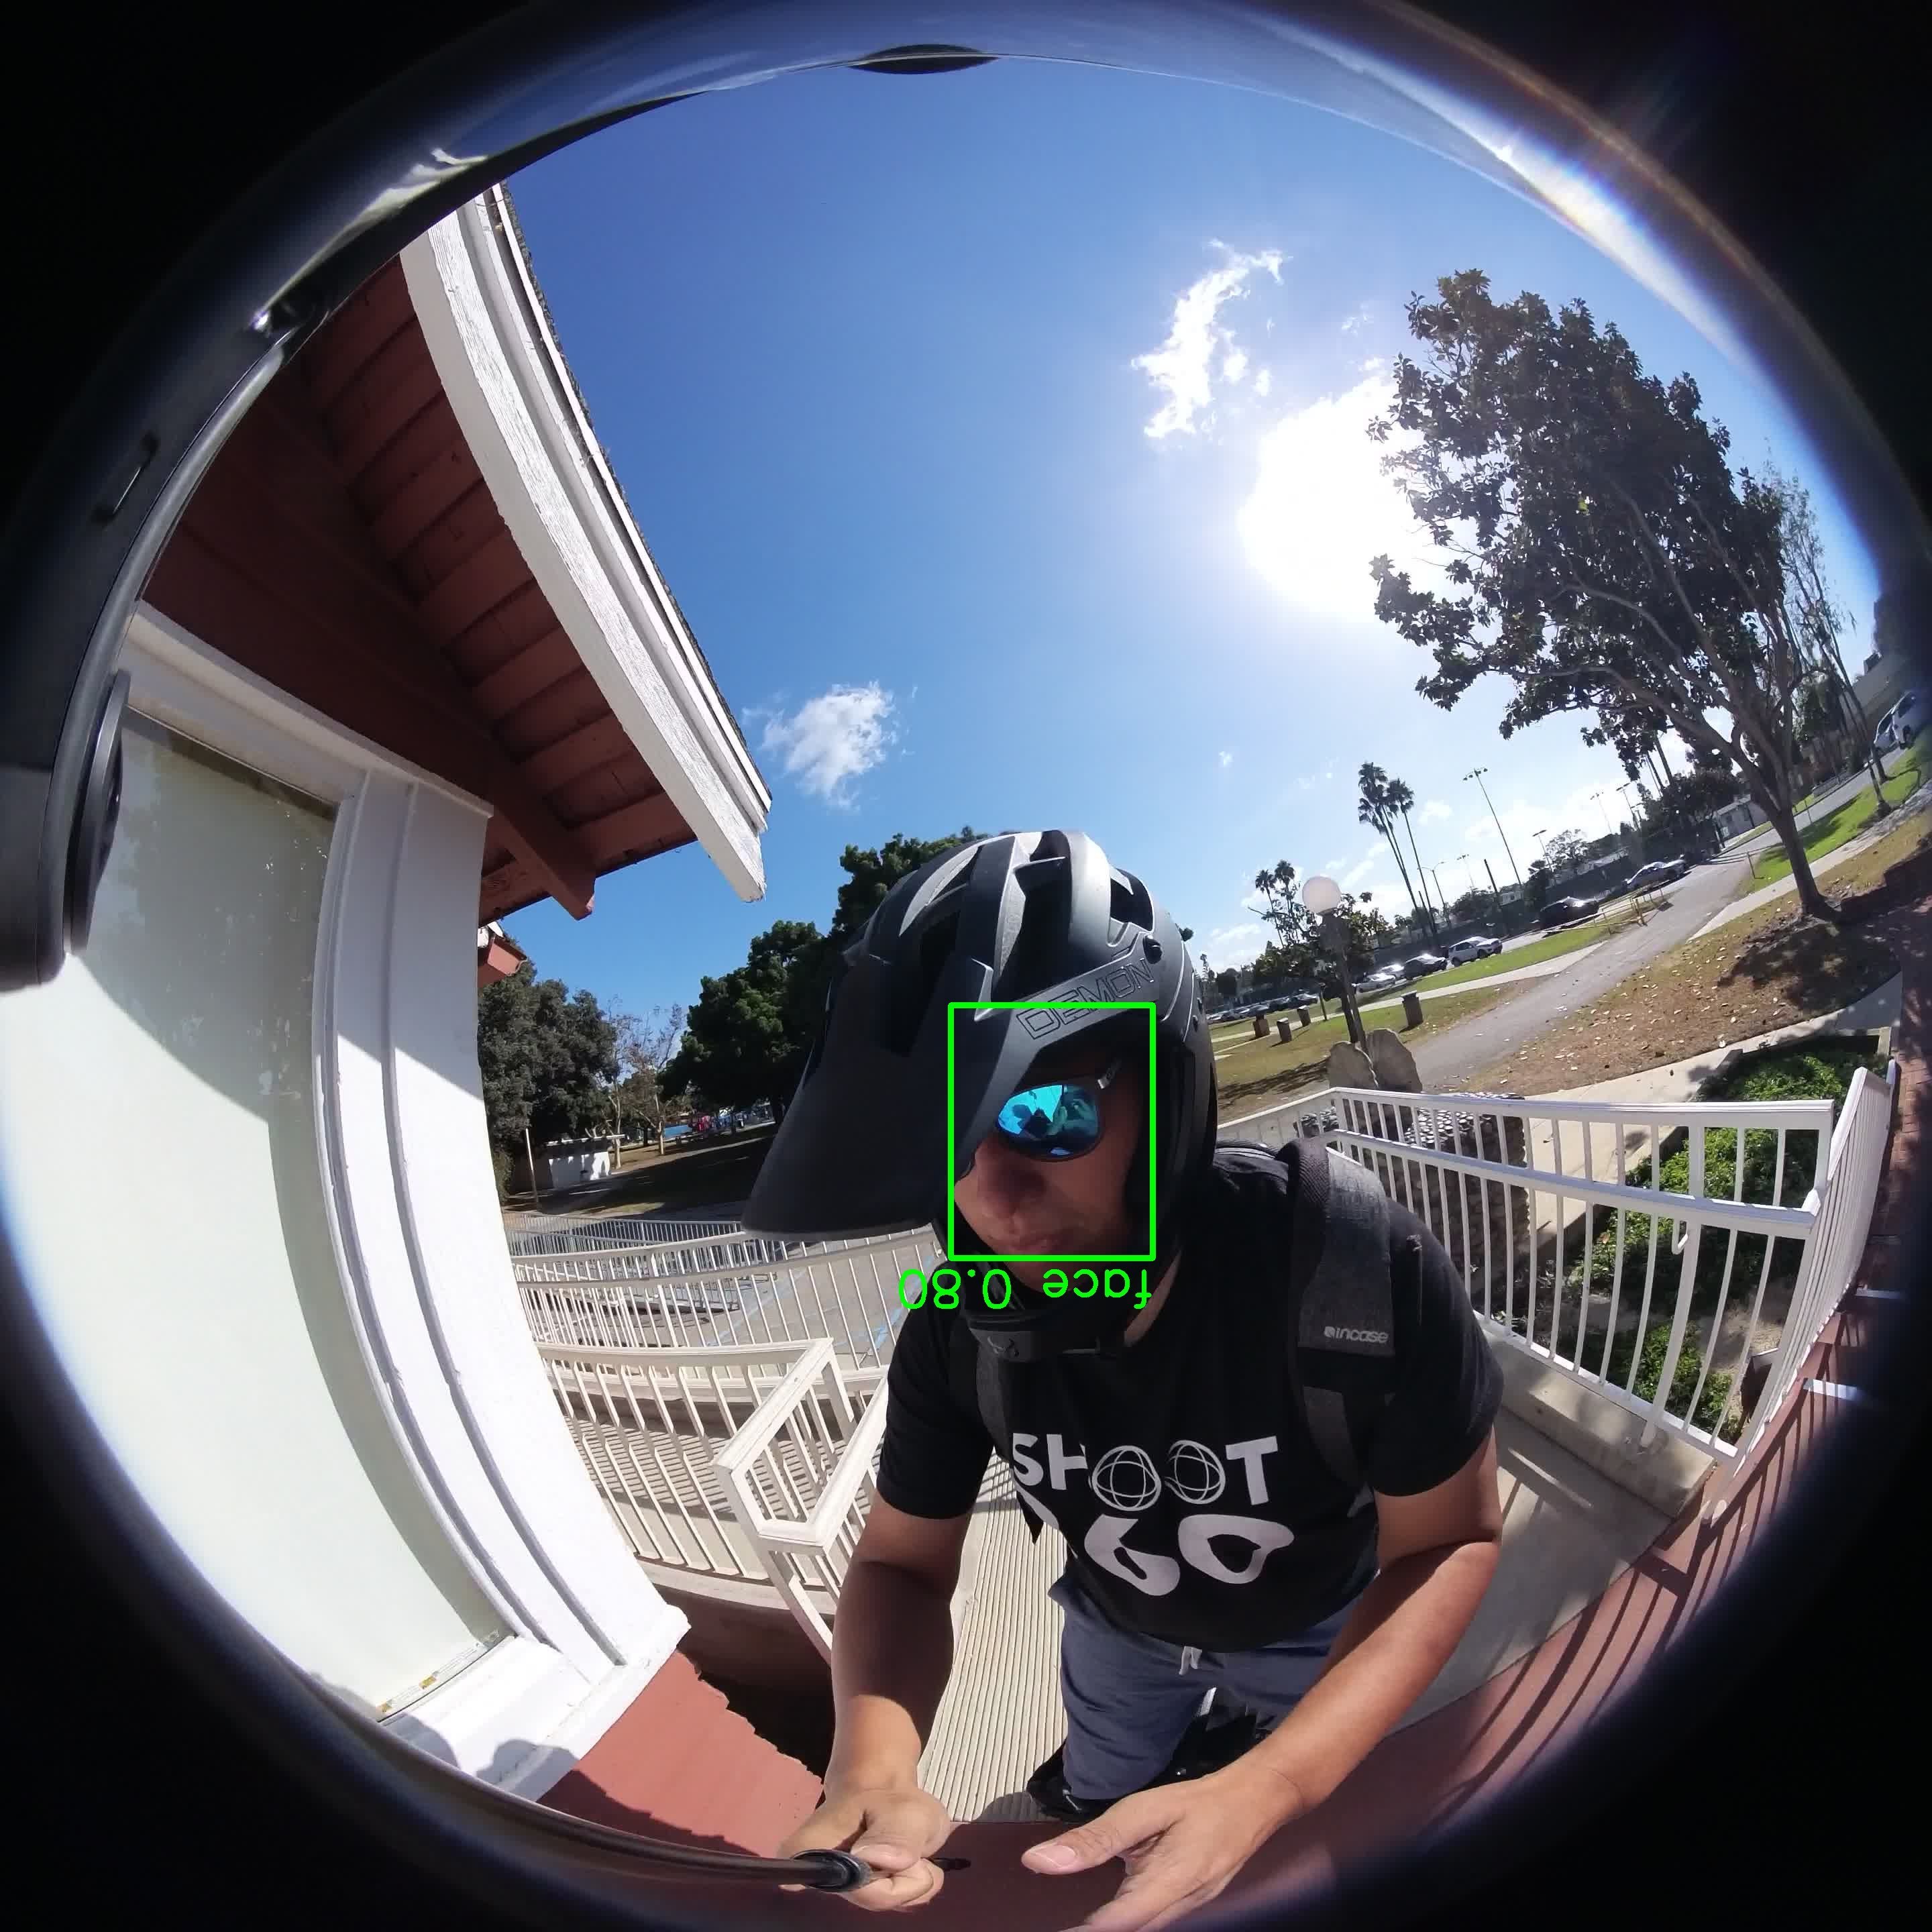 face · 0.80
Detect, box, blur
Stage one returns a box and a confidence for each face — here, face · 0.80. Stage two links those boxes across frames and burns an irreversible blur into the output. Toggle the frame to see the delivered result. Explore the full pipeline on the anonymization page.
Available as a standalone service — anonymization as a service.
Run it programmatically with the batch API.
One POST submits a whole batch for de-identification. The job runs asynchronously; you get a webhook when it clears human review, then download the anonymized output and its per-file certificate.
curl -X POST https://api.firsthand.dev/v1/anonymize \
  -H "Authorization: Bearer $FIRSTHAND_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "input_url": "s3://acme-dashcam/2026-09-23/*.mp4",
    "redact": ["faces", "plates", "screens"],
    "recall_target": 0.995,
    "review": "human",
    "source": "delete_after_delivery",
    "webhook_url": "https://acme.dev/hooks/firsthand"
}'{
"batch_id": "anon_9f2c71a4",
"status": "processing",
"files": 1284,
"redact": ["faces", "plates", "screens"],
"recall_target": 0.995,
"estimated_completion": "2026-09-23T18:40:00Z",
"certificate_url": null
}- Async batch jobs
- Submit one clip or a glob of hundreds of hours in a single call. Throughput scales with GPU allocation, not with headcount.
- Webhooks & polling
- Get a callback the moment a batch clears review, or poll GET /v1/anonymize/:id. No long-held connections.
- Per-file certificate
- Every completed batch returns a certificate_url — detector version, reviewer sign-off, blur settings, and measured recall per file.
- Idempotent & auditable
- Retries are keyed so a re-sent job never double-processes, and each file is checkable against its own record.
The batch API runs the exact five-stage pass described on /anonymization, including the human review step — endpoints and keys are provisioned per engagement.
Pipeline
Five steps. Spec to delivery.
Step 03 is the one most vendors leave out, and it is the reason you are not paying for footage you will throw away.
- 01SPECNamed skill list, coverage targets, accept/reject criteria
- 02CAPTURECalibrated rigs, vetted and trained operators, real environments
- 03VALIDATESync check, QA pass, reject and recapture — you see the reject log
- 04ENRICHDepth, body pose, hand pose, action segments, instance masks
- 05DELIVERRLDS, LeRobot, WebDataset, HDF5 — plus the data card
Engagement models
Start small, scale on the same pipeline.
Every engagement runs through the same managed service. What changes is how long it runs and how often you re-point it.
Each stage of the service is broken down — what happens, what you get, and how it is measured — on the end-to-end pipeline page. For the model-by-model view, see custom data collection for AI training, or go deeper on embodied AI training data. For the definition of the term itself, see what data collection as a service is. Deciding whether to run collection yourself instead? See in-house vs outsourced egocentric data collection.
How we prove it trains better
The only number that matters is the one downstream of the data.
Same architecture, same eval suite, same seeds — only the pretraining corpus changes. The protocol is fixed and public; measured head-to-head results publish once they reproduce independently.
We pretrain one fixed policy architecture on each corpus, then score it on a held-out manipulation suite with fixed seeds and a rubric we do not grade ourselves. Only the pretraining data changes between arms, and hours are reported so any win is visibly about fitness, not volume.
Measured results publishing Q4 2026. The methodology and full eval harness are open now.
- Architecture
- Identical diffusion policy, 210 M params, no per-dataset tuning
- Eval suite
- 40 unseen manipulation tasks, 20 trials each, fixed seeds
- Success criterion
- Task-completion predicate, scored by held-out rubric, not by us
- Confound
- The Firsthand arm is 1,200 h vs EgoScale 20,854 h — the delta is fitness, not volume
Case study
A bimanual loading policy that kept failing on half-full racks.
Anonymised at the buyer's request: a US humanoid lab, Series B, training a bimanual dishwasher-loading policy. Their footage was clean and their policy still failed the moment a rack was partially occupied.
- 620hours
- Validated hours delivered in 11 weeks
- 11skills
- Named skills in the spec, all cells filled
- +21pts
- Success rate on their internal dishwasher eval
- 7.4%
- Batch reject rate — recaptured at our cost
The lab had 4,000 hours of public egocentric footage and a policy that scored well in simulation. In the real world it stalled on any rack that was already half loaded, because almost nothing in the public corpora shows a person recovering from a bad grasp inside a cluttered fixture.
We wrote a spec with a hard quota: 15% of every batch had to be a failure and recovery — dropped plate, wrong slot, tine collision — with the recovery captured through to completion. That quota is the whole case study.
Their words, lightly trimmed: “The failure cases were the only part we couldn’t buy anywhere else, and they moved the eval more than the other 500 hours combined.”
Engagement timeline
- WEEK 0Spec written together: 11 skills, 6 kitchens, explicit failure-case quota of 15%
- WEEK 1Rig calibration on their object set — 34 SKUs of real crockery shipped to us
- WEEK 2First 50 h batch delivered in RLDS. They found a wrist extrinsics error. We recaptured 12 h.
- WEEK 4Cadence at 70 h/week. Coverage report per batch with the reject log attached.
- WEEK 11620 h delivered. Failure cases turned out to be the highest-value slice.
Anonymised with permission. Reference call available under NDA once a spec is scoped.
The sample
See the data before you talk to anyone.
Start with an unedited clip off the head camera, then the schema that ships on top of it — same enrichment layers, same license terms as a production batch. No form, no call, no NDA.
Real footage first, then the annotation schema that ships on top of it.
- Frame
- 960 × 540
- Length
- 8 s
- File
- 4.7 MB
- Audio
- Present in source, muted here
A transit segment — carrying a tool between floors. Exactly the footage staged datasets cut, and a reason policies fail to move between rooms. The image circle is letterboxed into a 16:9 canvas, so the black margins are the proxy container, not lost data.
A different episode, drawn from the schema rather than filmed — the clip on the left is RGB only, and depth, pose and masks arrive as separate synchronized streams. Download the pack to see them on real frames.
Carrying a vacuum downstairs — household chores, 8 s at 960 × 540
download ↓Watering plants · household 1 — household chores, 20 s at 360 × 360
download ↓Watering plants · household 2 — household chores, 10 s at 960 × 540
download ↓Practising guitar from tab — music practice, 1m 01s at 1280 × 720
download ↓Working soil in a raised bed — outdoor gardening, 1m 01s at 640 × 360
download ↓Browning mince on a gas hob — kitchen & food prep, 1m 01s at 640 × 360
download ↓Hand + body joints, masks, action segments, calibration
in the full pack ↓Rerun recording — every stream on one timeline
in the full pack ↓The full pack
2.4GB
Every stream at native rate, drawn from the same production batches you would license — not a curated highlight reel. Add an email and the download link lands in your inbox.
- 40
- episodes
- 4
- environments
- 8
- synced streams
Free and ungated after the clips above — no call, no NDA. Latest release: Egocentric-10K coverage release, warehouse + retail.
FAQ
Custom collection as a service, answered.
01What is custom data collection as a service?
It is a managed service where one provider runs the entire data collection for you — scoping the spec, recruiting and consenting contributors, supplying hardware, capturing, annotating, anonymizing, QA-ing, and delivering a licensed dataset. You describe what the model needs; the provider carries it end-to-end and hands over data you own.
02How is it different from a crowdsourcing platform?
A crowdsourcing platform gives you access to workers and leaves the spec, briefing, QA, and rights to you. A collection service owns the outcome: we write and enforce the spec, reject and replace failed takes, document consent per item, and deliver under a single buyer-owned license.
03What kinds of data can you collect as a service?
Our specialism is egocentric first-person video for embodied AI and robotics — hands, pose, depth, and synchronized multi-camera streams. The same managed pipeline runs speech and audio, image, video, text, and multimodal sensor collections.
04Do we need our own hardware or annotation team?
No. We supply and ship the capture hardware — from phone mounts to 360 head-mounts to the full instrumented rig — and run annotation, anonymization, and QA in-house. You only approve the spec and review the pilot.
05Who owns the data at the end?
You do. Every delivery ships under a perpetual, buyer-owned commercial license with signed contributor releases, an anonymization record, a visible reject log, and a data card documenting jurisdictions.
06How do engagements start?
With a short description of the gap. We return a scoped estimate — reach, timeline, and price — and usually recommend a pilot batch first, so you can validate the data against your own evals before committing to volume.
Request a quote
Tell us what you're training.
We quote per engagement rather than off a rate card, because price depends on which environments you need, how thin our coverage is in them, and how dense the annotation has to be. Fill this in and you get real numbers back.
- Reply time
- One business day, with a scoped estimate
- You receive
- Hours, price, delivery date, coverage cells to fill
- First call
- 30 minutes, technical, no deck
- Then
- A written spec you own, whether or not you buy
- Billing unit
- Validated hours only — rejects are never billed
Or skip the form entirely — support@cloudpano.com. A research engineer reads it, not a sales inbox.
Hand us the problem. Keep the dataset.
No finished spec required. You will get a scoped estimate with reach, timeline, and price — and a pilot batch — before any commitment.