Embodied AI
Training data for models that act, not just look.
- Core modality
- Egocentric video
- Streams
- RGB · depth · IMU · pose
- Sync ceiling
- Under 2 ms verified
- License
- Buyer-owned
What it is
The sensor record of doing, not describing.
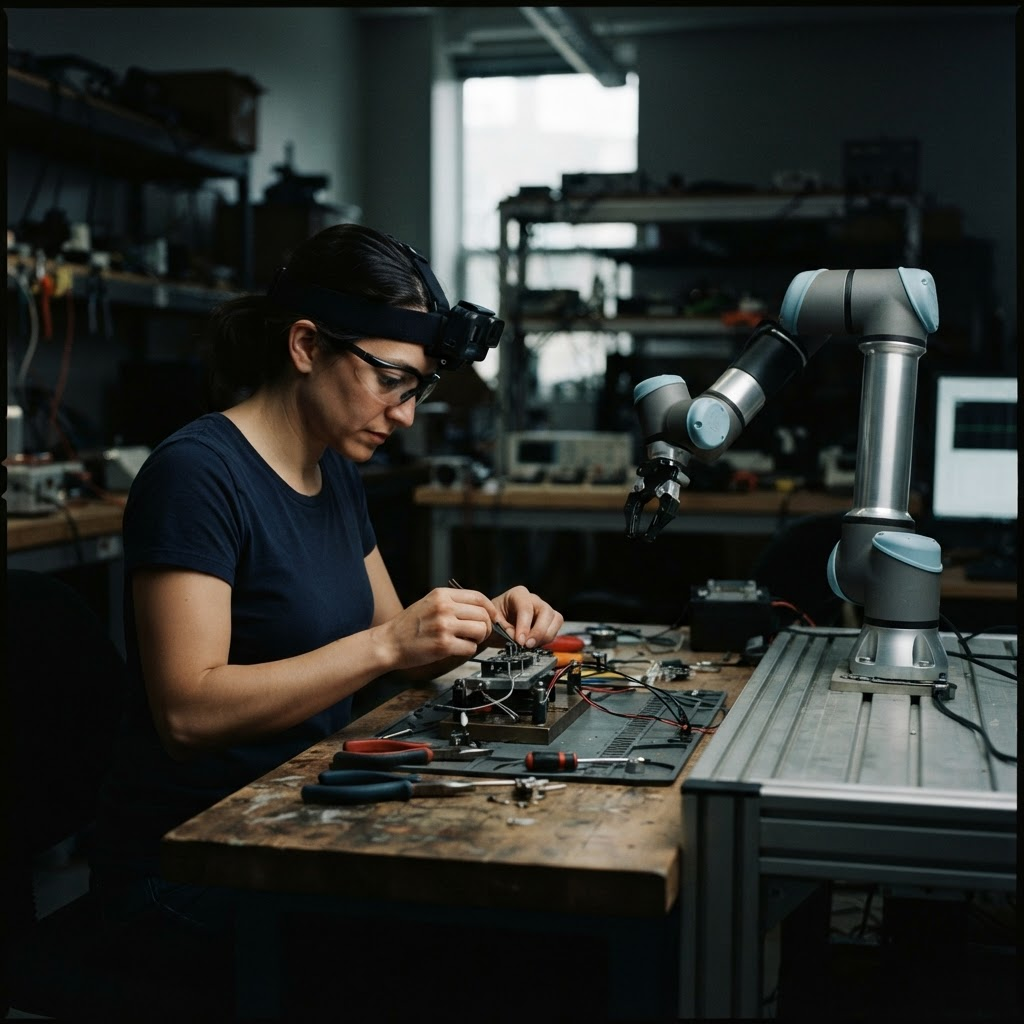
Embodied AI training data captures an agent acting in the physical world — the first-person view plus the depth, motion, and pose that make the action learnable.
A model that only ever saw internet video learns what tasks look like. A model that learns to act needs the streams underneath the picture: how far away the handle was, how the wrist rotated, when the fingers made contact. Those are exactly the signals that scraped footage throws away and that we capture on purpose — aligned, timestamped, and tied to a consent record you can show your counsel.
We collect it the same spec-first way we run every program: you name the tasks, environments, viewpoints, and edge cases; we source and capture against them; and anything that misses the spec or cannot be de-identified is discarded rather than shipped at a discount to pad a count.
What's in it
Aligned streams, one clock.
Choose the streams your architecture consumes. On the egocentric rig they are hardware-triggered onto a shared clock so the relationships between them survive into training.
- First-person video
- Head-mounted RGB that matches what the agent sees — hands entering frame, occlusion during grasp, motion during reach.
- Metric depth
- Per-frame depth aligned to the RGB stream for 3D perception, reaching, and collision reasoning.
- Hand & body pose
- 3D keypoints tracked through the sequence, with visibility flags and contact events for manipulation learning.
- Motion & IMU
- Accelerometer and gyroscope streams hardware-timestamped on the same clock as the cameras.
- Wrist & multi-view
- Optional wrist cameras and third-person views of the same activity for cross-view training.
- Action segments
- Optional labeled sub-actions and transitions — the reach, grasp, and release most datasets edit out.
The full sensor set, calibration, and sync-measurement method live on our capture methodology page, and shipping coverage is on the dataset catalog.
Where teams use it
From imitation learning to world models.
- Imitation learning and behavior cloning from human demonstration
- World models and video prediction for planning
- Vision-language-action (VLA) and robot foundation models
- Manipulation and grasping policies trained on real contact
- Activity and intent understanding for assistive agents
- Sim-to-real grounding with real-world edge cases
FAQ
Questions teams ask first.
- What is embodied AI training data?
- Embodied AI training data is the sensor record of an agent acting in the physical world — first-person video plus the aligned depth, motion, and pose streams that let a model learn how perception connects to action. Unlike scraped web video, it is captured deliberately against a spec, time-synchronized, and consented, so a policy can learn cause and effect rather than just appearance.
- Why is egocentric video the right foundation for embodied AI?
- Because the agent acts from a first-person viewpoint. Egocentric footage puts the hands, the manipulated objects, and the occlusions in exactly the frame the policy will see at inference, so the training distribution matches deployment. Third-person video teaches what a task looks like from outside; egocentric video teaches what it feels like to do it.
- How synchronized are the streams?
- On our egocentric rig every stream is hardware-triggered onto one clock and the median cross-stream offset is verified under two milliseconds. Streams that merely sit in the same folder but drift against each other are close to useless for manipulation, so we measure and report the achieved offset with every batch.
- Can you collect data for a specific task, environment, or robot?
- Yes. We collect against a named spec — the exact actions, environments, viewpoints, and edge cases you need — sourced from a vetted global crowd across 150+ countries and 500+ languages. If your need does not fit an existing environment, our custom-collection service designs the whole program around it.
- What formats do you deliver in?
- RLDS, LeRobot, WebDataset, HDF5, zarr, and Rerun .rrd, with int64 nanosecond timestamps per stream and calibration included. Converters ship as readable source so you can retarget to your own training loader.
Scope embodied AI data against one task.
Bring the policy you are training and the task it has to learn. You will get a scoped estimate — streams, environments, reach, timeline, and price — before any commitment.