A 24-joint 3D skeleton
Body pose ships as body_joints in the annotations group, with 24 joints of 3D coordinates per frame, on the same timeline as the video.
Body pose collection
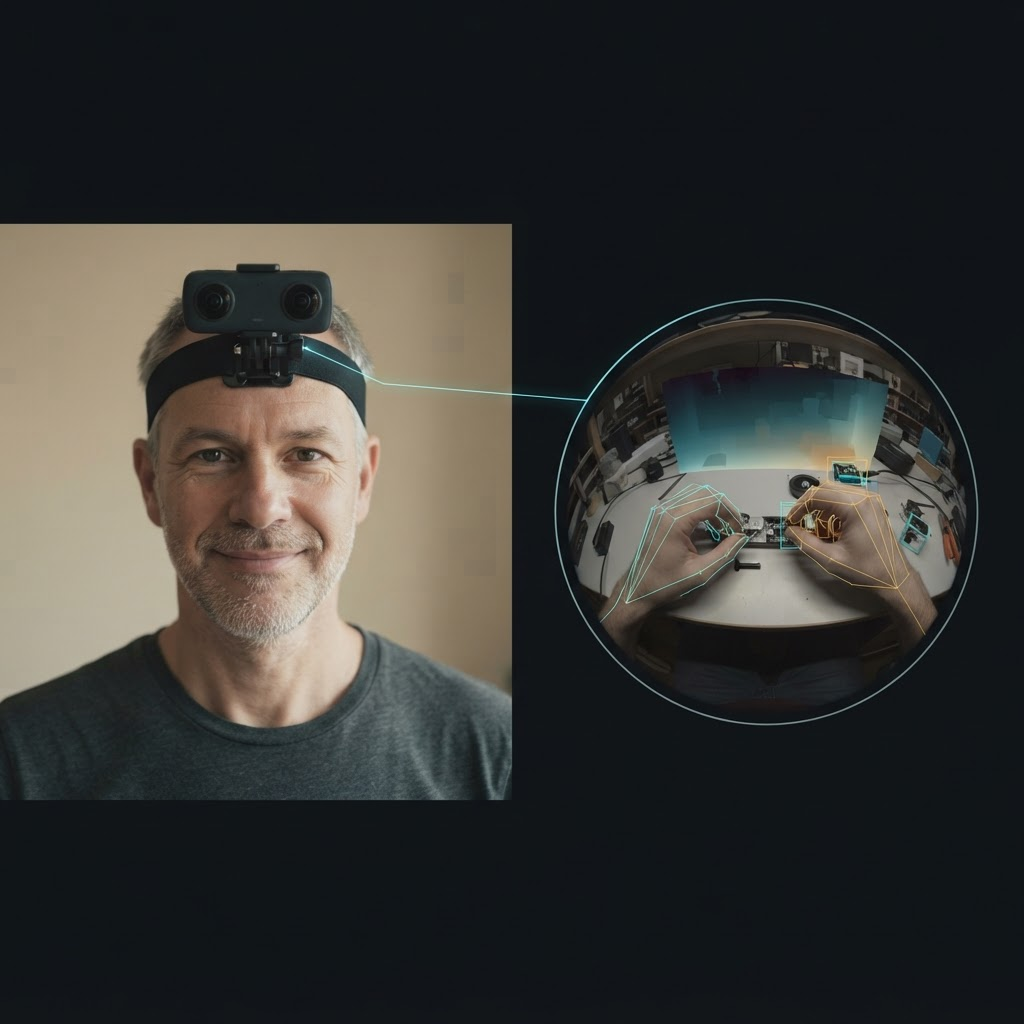
What a body pose delivery includes
Body pose ships as body_joints in the annotations group, with 24 joints of 3D coordinates per frame, on the same timeline as the video.
Hand joints (21 per hand, with a visibility flag) and 200 Hz wrist IMUs ship on the same clock, so body, hands and wrists can be read together.
Streams are hardware-triggered onto one PTP domain with int64 nanosecond timestamps, so pose and video can be aligned from the data itself.
In the LeRobot v2.1 export, body joints follow the hand joints in observation.state, in a fixed order documented on the format page.
Definition
Egocentric video with body pose data is first-person task footage delivered together with the 3D positions of the wearer’s body joints over time. On Firsthand’s rig that is a 24-joint skeleton per frame, delivered as body_joints in the annotations group of the episode schema, on the same timeline as the video, the hand joints, depth and IMU.
This page sells the collection: fast, on-demand, custom collection scoped to your skill spec, with body pose delivered beside the video. It is not the definition and it is not annotation of footage you already own. The body pose estimation glossary entry defines the term, and the keypoint and pose annotation page covers labeling. Here the focus is what you receive and how to order it.
Why it matters
The site’s glossary states the case: humanoid and other embodied-AI policies need more than hand geometry, because a task like carrying, reaching or stepping around an obstacle depends on torso orientation, stance and arm extension together. It adds that body pose matters most for humanoid and whole-body manipulation training rather than fixed-base arm tasks.
The humanoid pages say the same thing from the data side: whole-body pose alongside the hands carries the balance and locomotion context a humanoid action depends on, and body pose with IMU adds stance, reach and the transfer between locomotion and manipulation. The site states this dependency but does not quantify how much body pose changes model performance, and this page does not either.
Pose fields
Body pose is delivered as body_joints in the annotations group, listed beside hand_joints, hand_visible, contact_events, instance_masks, objects, action_segments and gaze_target. The site’s format FAQ gives its shape as bodyJoints[24][3]: 24 joints with three coordinates each. The stream list describes it as 3D, root-relative and world-frame, with torso and forearm chains resolved, and the glossary describes the coordinates as metric and captured in the head-camera frame.
The two frame descriptions are both on the site, so which frame a given delivery uses is confirmed in the spec rather than assumed. The body pose field sits next to the hand fields, which are better specified: float32 [T, 2, 21, 3] in metres in the head-camera frame, with hand_visible flagging occluded joints. The first table lists each field and what the site states about it.
Body, hand and wrist
They are three different signals. Body pose is the larger skeleton, covering torso, arms and legs, and is used for whole-body motion such as stance, reach and stepping. Hand pose is the 21 joints per hand used for fine manipulation, meaning grasp shape and contact at the object. A wrist trajectory is the motion of each wrist recorded by a 6-DoF IMU at 200 Hz.
The site delivers all three together and keeps them distinct. This page claims for body pose only what the site states for body pose: 24 joints, 3D, in the annotations group. The per-joint visibility flag and the 21-joint count belong to hand pose, and the IMU rate belongs to the wrist streams. The second table sets the three side by side.
Capture
The site states that 3D hand and body pose are captured live on the rig rather than reconstructed after the fact, and lists body pose in the enrichment stage of its pipeline, with depth, hand pose, action segments and instance masks. The rig itself is a global-shutter head camera at 4K and 60 fps with a 120° horizontal field of view, two wrist cameras at 1920×1080 and 60 fps, a depth stream at 848×480 and 30 fps in metric millimetres, and 6-DoF IMUs on the head and both wrists at 200 Hz.
What the site does not state is how the 24 joints are derived: which sensors or estimation method produce them is not described on any page. That is set per program in the skill spec, and you should ask for it if your model depends on it. The third table lists the rig streams that travel with body pose.
Sync
The glossary states that body pose is captured synchronized with hand pose, depth and RGB under two milliseconds. The capture page describes the mechanism: the head-mounted stereo pair, both wrist cameras, the depth sensor and the IMUs run on one PTP clock domain, and every delivered stream carries int64 nanosecond timestamps in that domain.
The stated figures are a 1.12 ms median and 1.94 ms p99 against a 2.0 ms ceiling, and a stream that exceeds the ceiling for more than three consecutive frames is a reject reason. The frame rate of the body_joints stream itself is not stated and is set per program.
Formats
The episode schema is the canonical layout, and its annotations group lists body_joints; HDF5 and zarr mirror that layout. In the LeRobot v2.1 export, hand and body pose are flattened into a single observation.state vector, with 2×21×3 hand joints first and then 24×3 body joints, in that order. The guide on converting between RLDS and LeRobot says to keep that ordering and to check the vector against it.
RLDS names hand_joints as a step key, but body pose is not a named RLDS step key on its own. The WebDataset page lists hand_joints, action and contact_events for its annotation file and does not mention body joints. How body pose is laid out in those two formats, and in Rerun .rrd, is not stated, so name your loader in the spec. The fourth table summarizes this.
Quality and consent
Body pose is part of the validated hour only through the checks the site defines for every episode: sync within the ceiling, calibration solved and within drift tolerance, coverage cells filled and consent documented. A separate accuracy gate for body joints is not stated, and no body pose accuracy figure is published.
On consent, the contributor agreement the site describes covers derivative representations, including hand and body pose estimates, and those layers sit under the same consent as the video. Delivered data ships under a perpetual, buyer-owned license. Rejected episodes are recaptured at the provider’s cost.
Agreed per spec
Several body pose details are not fixed on this site and are agreed in the skill spec. The last table separates what the site states from what is set per program, so you know what to put in writing before the quote.
Getting started
Send the tasks, the environments and regions, and the delivery format you need, and name body pose in the streams and labels list. The site lists RGB as the baseline and the other streams as added where the spec calls for them, and says that hand pose, body pose, segmentation and action labels each add equipment, QA passes and cost, so order what the model consumes. If you have no written spec yet, the first draft is written with you on a call.
The order flow is spec, quote, Spec Pilot, then production. Where coverage for your tasks and regions is deep, the median time from signed spec to first validated batch is 48 hours; where it is thin, turnaround runs three to four weeks. There is no list price, and billing is per validated hour.
At a glance
Every collection runs through the same seven-stage end-to-end custom collection pipeline. End-to-end custom data collection is a managed service that takes an AI data need from problem to owned dataset in a single accountable pipeline.
Pose fields
| Field | What the site states | What it is used for |
|---|---|---|
| body_joints | In the annotations group; bodyJoints[24][3], 24 joints with 3D coordinates | Whole-body stance, reach and locomotion context |
| Body frame and units | Metric; head-camera frame (glossary); root-relative and world-frame (stream list) | Confirmed in the spec for each delivery |
| Body chains | Torso and forearm chains resolved | Arm and trunk motion during manipulation |
| hand_joints | float32 [T, 2, 21, 3], metres, head-camera frame | Fine manipulation: grasp shape and contact |
| hand_visible | Per-joint visibility flag for hands | Masking or down-weighting occluded hand joints |
| imu_wrist_l / imu_wrist_r | 6-DoF, 200 Hz, one per wrist | Wrist motion measured live |
| *_timestamp_ns | int64 nanoseconds per stream, shared PTP domain | Aligning pose to video from the data |
Body, hand and wrist
| Signal | What the site states | Typical use | Not stated |
|---|---|---|---|
| Body pose | 24 joints, 3D, per frame; annotations/body_joints | Stance, reach, carrying, stepping | Skeleton model, accuracy, body visibility flag |
| Hand pose | 21 joints per hand, metres, with per-joint visibility flag | Grasp shape and contact at the object | Accuracy figure |
| Wrist trajectory | 6-DoF IMU on each wrist, 200 Hz | Where the hand went, measured live | Pose derivation, frame, smoothing |
Rig streams
| Stream | What the site states | Relation to body pose |
|---|---|---|
| Head camera | Global-shutter, 4K at 60 fps, 120° HFOV | Reference frame for pose coordinates |
| Wrist cameras | Two, 1920×1080 at 60 fps | Hand-level view beside whole-body context |
| Depth | 848×480 at 30 fps, metric millimetres plus confidence | Pose is aligned to depth and RGB |
| IMUs | 6-DoF, 200 Hz, head and both wrists | Motion context beside body joints |
| Clock | One PTP domain, hardware-triggered | Body pose aligned under 2.0 ms ceiling |
Formats
| Format | What the site states | Set per program |
|---|---|---|
| Episode schema | annotations/ group lists body_joints beside hand_joints | Body joint frame and frame rate |
| HDF5 / zarr | Mirrors the episode schema layout | Anything beyond the format page |
| LeRobot v2.1 | observation.state: 2×21×3 hand joints first, then 24×3 body joints | Nothing beyond the stated ordering |
| RLDS | hand_joints is a step key; body pose is not a named step key on its own | Where body pose is stored |
| WebDataset | Annotation file lists hand_joints, action, contact_events | Where body pose is stored |
| Rerun .rrd | Listed as a delivery format | Body pose layout |
Agreed per spec
| Detail | What the site states | Where it is set |
|---|---|---|
| Joint count | 24 joints | Stated; confirmed in the spec |
| Skeleton model and joint names | Not stated | Set per program in the skill spec |
| Body pose accuracy | Not stated; no figure published | Set per program in the skill spec |
| Body joint visibility flag | Stated for hands only | Set per program in the skill spec |
| Sensors or method behind the joints | Captured live on the rig; method not stated | Set per program in the skill spec |
| Hours, price and turnaround | No list price; median 48 h where deep, three to four weeks where thin | The quote and the Spec Pilot |
FAQ
Sources
Tell us the tasks, environments, the body and hand fields your model needs, and the format you load from. A first validated batch arrives in a median of 48 hours where coverage is deep.