Now recruiting capture teams worldwide. Get paid to record first-person video of real work.

Apply to capture

Lunchbox packing

Egocentric Lunchbox Packing Data

Pick up an item, set it into a compartment, and move on to the next: packing a lunchbox is a run of small placements into a space that is smaller than the room around it. We collect first-person food container packing video on demand for the one catalog row that names this work, to a written spec, as a handheld gripper compartment packing dataset when the spec names it, with synchronized streams, action segments, anonymization and a buyer-owned license. It is fast, on-demand custom kitchen data collection, and custom collection at scale through a network of thousands of capture providers, for a consistent, recurring data flow to labs.
Catalog row
"Pack a lunchbox": Medium, Available on request
Catalog capture setup
Multiview rig + handheld grippers
Streams
Ten, synced under 2 ms
License
Perpetual, buyer-owned
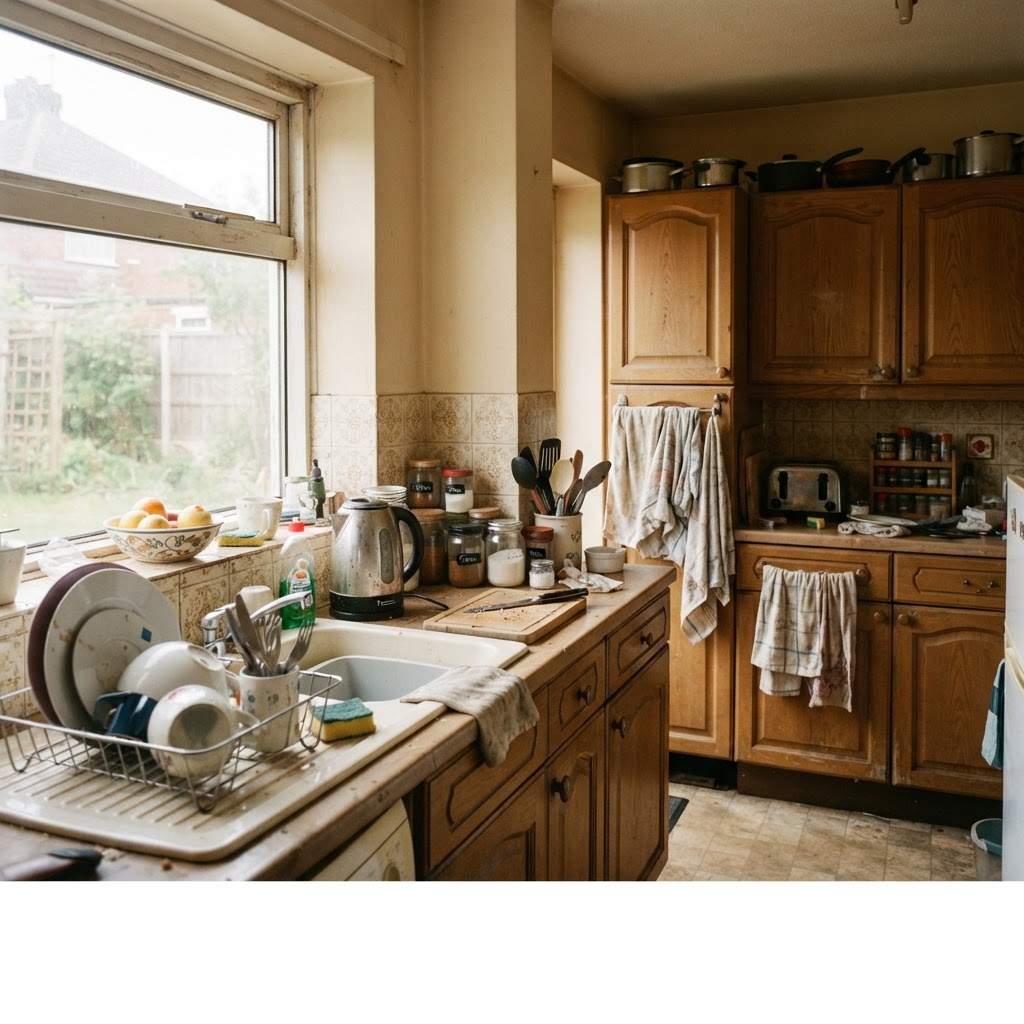
A real lived-in domestic kitchen with everyday clutter on the countertops, seen from the first-person viewpoint of someone preparing food.
A counter-top food-prep setting, shown to illustrate the view a robot working at a counter would have. The catalog lists its lunchbox row in a Working Kitchen Set described as a stovetop, counter, sink, dishwasher, utensils and food props, and the site does not describe a specific kitchen or box for the row. The image is a setting illustration, not a delivered clip of this task.

Requirements

What does lunchbox packing need that a generic kitchen clip does not?

01

Both hands, the items and the box in view together

Packing a lunchbox puts items in the hands and a box with compartments on the work surface. First-person capture keeps both hands and the box in frame, and the two wrist cameras add a closer view of the hands than the head camera alone. 3D hand pose carries a per-joint visibility flag, so a finger hidden behind an item or a compartment wall is flagged rather than guessed.

02

A spec that names the placement, not just "packing"

The site’s skill-spec guide says to name the verb and the noun rather than a broad activity. A spec for this task names the step and the item, such as pack an item into a compartment, and where one completed placement starts and ends, so each can become its own labeled segment.

03

Small spaces where the hands hide the work

Setting an item into a compartment puts the hand over the very spot a camera needs to see. The site’s answer is stated in general terms: hand pose is delivered for both hands with visibility flags, contact events mark the moment the hand meets an item, and action segments mark where each step begins and ends.

04

Reject rules written before capture, not after

An item is rejected when the manipulated object is out of frame for too much of the episode, when depth is invalid over too much of the manipulation region, or when an undocumented bystander appears. The thresholds are agreed in the spec, so the batch is judged against terms you signed.

Definition

What is egocentric lunchbox packing data?

Egocentric lunchbox packing data is first-person video of a person packing a lunchbox with items into compartments, recorded from the contributor’s own point of view with synchronized sensor streams alongside. The frames show the hands, the box and the items going into it, rather than a distant view of someone in a kitchen. On this site it is a custom collection: you name the task, the setting and the capture tier, and capture is run to a written skill spec.

The data is human capture. A paid, consented contributor does the task, and nothing here is robot or teleoperation data or a fixed corpus you download. This page is about one task, the one the catalog calls "Pack a lunchbox". It sits beside egocentric packing and kitting data, which covers cartons, bagging, sealing and kits, beside egocentric sandwich and salad assembly data, which covers assembling food, and beside egocentric meal plating and serving data, which covers dishes and trays. The subject here is a single container with compartments being filled.

People reach this topic through several phrasings: egocentric lunchbox packing data, first-person food container packing video, a handheld gripper compartment packing dataset, or custom kitchen data collection. They describe one request from different angles, and the work is the same: write down the task, collect it on demand, and receive validated episodes. A note on wording: the catalog row says pack a lunchbox with items into compartments. It does not say which items, how many compartments or what the lunchbox looks like, so this page names none.

Why it matters

Why do robots need first-person video of packing a lunchbox?

A published robot foundation model paper, GR00T N1, linked in the sources below, describes a data pyramid with web data and human video at the base, synthetic data in the middle and real robot trajectories at the top. First-person human video of packing sits in that base layer. Human capture does not replace robot data, and this page does not claim that it does.

Packing into compartments is a placement problem with an order inside it: an item has to be picked, carried and set into a space that is smaller than the room around it. The site describes smaller-scale packing in retail, food and office settings and lists packing a lunchbox into compartments among those rows. A clip with a lunchbox somewhere in frame does not carry what a policy needs. The hands, the items and the box have to be present, and the episode has to say where each placement starts and where it ends.

A published model write-up, GEN-0, also linked in the sources, puts it this way: "data quality and diversity matters more than sheer volume." For lunchbox packing that points at the spread of items, boxes, settings and people your spec names. A custom collection lets you aim at the placement your model is missing, rather than hoping a broad collection happens to contain it. This page makes no claim about how much footage of this task exists elsewhere, and it states no training outcome.

The catalog row

Which lunchbox packing task does the catalog list?

The first table below reproduces the lunchbox row of the site’s commercial task catalog, in the Food & Beverage sector, together with five neighbouring rows from the same set. The environment is the Working Kitchen Set (food prep), described with the examples stovetop, counter, sink, dishwasher, utensils and food props. The row is named "Pack a lunchbox" and reads "Pack a lunchbox with items into compartments." It is rated Medium, its capture setup is "Multiview rig + handheld grippers", and its status is Available on request.

Available on request means the work is scoped and recruited to spec when a buyer asks. It is not a statement that footage of this task has been delivered, and the site states no delivered hours of lunchbox packing, so this page claims none. It is also why this is custom collection, not an off-the-shelf purchase.

The catalog does not list closing or sealing a lunchbox, unpacking one, labeling it, or packing it into a bag or carton as tasks, so this page does not describe them as available. If your model needs one of them, it is settled in a Spec Pilot rather than assumed. The site names no item, container type, brand or kitchen for this row, and it lists capture at your own facility as not offered.

Neighbouring pages

How is this different from packing and kitting, sandwich and salad assembly and meal plating?

Several pages on this site sit near this one, and the second table below sets them side by side. Egocentric packing and kitting video data covers packing cartons, bagging and wrapping items, sealing and labeling, and building kits from parts, at pack benches and kitting stations. Its catalog table lists "Pack a lunchbox" as one row among containers and mailers, so lunchbox packing is named there, but as one row in a broad family and not as that page’s subject.

Egocentric sandwich and salad assembly data covers assembling food by hand, with a salad row rated Medium and an order assembly row for burgers, wraps and sides rated Easy. It names "Pack a lunchbox" only as a neighbouring row and says neither it nor "Slice + spread" is stated as a sandwich or a bowl. Egocentric meal plating and serving data covers plating dishes, portioning food and serving to a guest or table. This page is the one whose subject is the lunchbox row itself.

Egocentric baking and dough handling data, for "Knead + roll dough" and "Measure + mix", is the other neighbour from the same Working Kitchen Set. The distinction is the task and what the episode ends with: here, items set into the compartments of one box. Nothing on the site states that these tasks share labels, items or contributors, so none is claimed.

Episodes

What does each lunchbox packing episode contain?

Each attempt is delivered as one episode, and a packing task needs a decision up front about what one attempt is: one item placed, one compartment filled, one lunchbox packed from empty to full, or a longer run that strings several lunchboxes together. The site does not set that length, so the skill spec does. Inside the episode, the synchronized streams run from start to end, and action segments divide it into labeled spans.

A spec might cut a lunchbox episode from the first item picked up to the last item set into a compartment, as the catalog row describes, with one action segment per placement. That is an illustration of how a spec can cut an episode, not a stated duration. Whether the box starts empty, whether items start on the counter or in a container, and whether each placement is its own segment are spec decisions.

The setting behind this row is the Working Kitchen Set, captured with a multiview rig and handheld grippers according to the catalog. How many items, boxes, people, kitchens and conditions you want covered is set in the spec, along with whether you want a few long runs or many short ones.

Capture setup

What capture setup and streams are used?

A lunchbox collection uses the same capture stack as every Firsthand program. The instrumented tier is a head-mounted stereo rig that records first-person RGB, with a metric depth stream recovered from the calibrated stereo rig rather than from a standalone depth sensor, and 6-DoF IMU data at 200 Hz from head- and wrist-mounted sensors. The wider stack is ten streams: a 4K head camera, two wrist cameras, depth, IMU, 3D hand and body pose, instance segmentation and action labels, hardware-aligned under 2 ms. The two wrist cameras give a closer view of the hands than the head camera alone, which is useful where both hands work close to the box.

Every stream is hardware-triggered onto one PTP clock domain, so depth, motion and hand pose line up with the same video frame rather than being approximated afterwards. The rig is calibrated twice per session, before capture starts and after it ends, and an episode is accepted only if RMS reprojection stays under 0.28 px. The catalog lists a different capture setup for this row, a multiview rig with handheld grippers, and the site does not describe the grippers further. Which tier applies to your program is set in the skill spec, and this page does not claim that the head-mounted stack and the catalog setup are the same thing.

The sample data outputs page shows the delivered shape of this stack on a ten-second home-baking recording filmed in the US, with the IMU rows for the same ten seconds. Faces are blurred and the web clip is downscaled to 1080 × 1080, while the delivered files are the full 4608 × 4608 frame. The site does not say that clip shows packing, so treat it as a reference for the file format, not a claim about this task. Force and tactile readings are not among the streams, nothing measures how full a compartment is, and no robot or teleoperation data is captured.

Labels

How is lunchbox packing data labeled and delivered?

Inside each episode, action segments divide the recording into start- and end-timestamped spans, each carrying start_ns, end_ns, verb and noun. For this task a segment can be one placement as written in the skill spec, so a packed box becomes a run of labeled steps rather than one long clip. The other standard fields are hand_joints and hand_visible for 3D hand pose, contact_events for the moment the hand meets an object, objects, and instance_masks, stored at the depth resolution of 848×480 so they line up with the depth stream.

Hand pose is delivered for both hands, 21 joints per hand, with a per-joint visibility flag for occluded fingers. That is the label that carries how the hands pick, carry and set an item. The site describes contact events as the moment the hand meets an item, and it does not say whether the lunchbox lid, a compartment wall or the counter counts as the item, so the spec is the place to settle what a contact event means for your task. The one language field the site ties to Firsthand capture is a single task instruction per episode.

The site does not list labels for the lunchbox itself. There is no stated label for item type, compartment, fill state, order of placement, a task-completion score, or contact force. Catalog descriptions such as pack a lunchbox with items into compartments describe the task the contributor performs, not a delivered measurement.

Stated limits

What does the site state about the hard parts of recording this task?

Several limits the site already states apply to packing into compartments, and several it leaves open. Each stated limit below appears elsewhere on the site rather than being introduced here.

Hand occlusion is the first. Fingers disappear behind objects in manipulation, which is why 3D hand pose carries a per-joint visibility flag. Depth is the second. The site says depth degrades on wet and reflective surfaces and handles that with per-frame confidence maps. The site does not say how depth behaves on a lunchbox, its lid or its compartment walls, and it does not say that this row involves wet or reflective surfaces. Masks are the third. Per-frame instance masks are shipped where the spec calls for them, and the site gives no mask accuracy figure for small items or compartment edges.

The fourth is the set of machine-checked reject criteria. An episode is rejected for a sync breach beyond the ceiling for more than three consecutive frames, calibration drift beyond tolerance, the manipulated object out of frame for more than 15 percent of the episode, more than 35 percent invalid depth pixels in the manipulation region, an undocumented bystander, or a mismatch against the named skill spec. A human reviewer then checks each episode against the task spec. Packing keeps the hands close to a small box, so what counts as the manipulated object, the item, the lunchbox or a compartment, is worth settling in the spec.

Also not stated: how a packed lunchbox is judged complete, or how many items or compartments a typical episode covers. If your policy depends on either, say so at the start.

QA, consent and anonymization

How do QA, consent and anonymization apply?

Validation runs against signed accept criteria written into the spec before capture. Each batch goes through per-batch QA and a reject log ships with it. Only footage that clears the criteria is billed as a validated hour, and rejected items are recaptured at our cost. Many teams start with a Spec Pilot, a small, fast first batch that proves the spec and the accept criteria on real footage before volume scales.

Every contributor signs a written release before capture, and each delivered episode links to that record through consent artefact IDs in the batch data card. The consent chain has six checkpoints, from before capture to after delivery, and a break at any one discards the footage rather than shipping it at a lower grade. At ingest, automated detection finds faces, plates and screens and blurs them irreversibly, and speech is scrubbed of names, addresses and card numbers while ambient audio is kept. A human reviewer confirms that no un-consented person is identifiable in any frame, and footage that cannot be de-identified is discarded. The anonymization record is delivered with the data.

The site states no food-safety or hygiene protocol and no food-handling certification for this row, and this page does not describe one. If your program needs terms about who performs the work or the conditions under which it is done, raise them when you scope it. None of this is legal advice, and the executed agreement controls.

Delivery and speed

How fast can a custom lunchbox packing dataset be collected?

From signed spec to first validated batch, the timeline is a median of 48 hours where coverage is deep and three to four weeks where it is thin and contributors need to be recruited first. Speed comes from a warm pipeline, not from cutting consent, review or anonymization. The site does not say whether the Working Kitchen Set counts as deep or thin coverage, so ask which timeline applies when you request the quote. After the first batch, on-demand top-ups run against the same accept criteria, so you can add more items, boxes, people or conditions without rewriting the spec. The site does not state a turnaround for those later batches, so plan them in your quote.

For programs that need volume, the site describes custom collection at scale through a network of thousands of capture providers, for a consistent, recurring data flow to labs. It states no provider count, hours or cadence beyond that wording, and it does not say that any lunchbox hours already exist.

Delivery is in the format your stack already reads: RLDS, LeRobot, WebDataset, HDF5, zarr or Rerun .rrd, or raw streams with metadata. Readable converter source ships alongside the data so the schema can be retargeted to your own loader. Collections are billed per validated hour. The license is perpetual, irrevocable and worldwide, with the data buyer-owned and non-exclusive by default. Training, evaluating, fine-tuning and deploying models, including commercial ones, is permitted, and exclusivity is available as a separate term. The executed agreement controls, and the site does not publish a price list, a minimum order or a batch size for this task.

Not stated

What does a lunchbox packing collection not include?

Where this site does not state something, this page says "not stated" rather than filling the gap. The streams table below separates what is delivered from what is not stated. There is no listed label for item type, compartment or fill state, no force or tactile stream, and no claim beyond the catalog row and neighbours quoted above. Nothing here claims a training outcome or a model improvement.

The tradeoff to plan for is the embodiment gap between a human pair of hands setting items into a box and a robot platform doing the same, which retargeting or pairing with robot data has to close. Counts of contributors, hours and items are set in your skill spec.

Getting started

How do you start a lunchbox packing pilot?

Describe the placements, the setting and the variation or failure cases your pipeline is missing. That becomes a written skill spec, quoted for reach, timeline and price before any capture begins, and most programs run a Spec Pilot first. The scoping checklist below maps the parts of a skill spec onto a lunchbox request.

Three choices matter most for this task. Name the step and the item rather than a broad activity, because that is what lets each placement become one action segment. Name the setting and the capture tier, since the catalog lists the Working Kitchen Set row with a multiview rig and handheld grippers. And name where the episode starts and stops: one item, one compartment, one full box or a longer run, since the site does not set an episode length.

Capture setup

What is the capture setup for a lunchbox packing collection?

The capture setup as stated on this site, applied to this task. Counts of contributors and hours are set in the skill spec.
PartAs stated on this site
Instrumented rigHead-mounted stereo rig worn by the contributor; first-person RGB
StreamsTen: 4K head camera, two wrist cameras, depth, IMU, 3D hand and body pose, instance segmentation, action labels
SyncHardware-triggered onto one PTP clock domain; aligned under 2 ms
DepthMetric depth recovered from the calibrated stereo rig; per-frame confidence maps are shipped; degrades on wet and reflective surfaces
IMU6-DoF at 200 Hz from head- and wrist-mounted sensors
CalibrationTwice per session; accepted only under the 0.28 px RMS reprojection gate
Hand pose21 joints per hand with a per-joint visibility flag
MasksPer-frame instance masks where the spec calls for them, stored at 848×480
Catalog capture setupMultiview rig with handheld grippers for the "Pack a lunchbox" row

Every collection runs through the same seven-stage end-to-end custom collection pipeline.

Working Kitchen Set rows

Which lunchbox and neighbouring kitchen tasks does the catalog name, and what is captured?

Six rows from the Working Kitchen Set (food prep), reproduced as the catalog states them, in the Food & Beverage sector. The set is described with the examples stovetop, counter, sink, dishwasher, utensils and food props. Only the first row names a lunchbox.
Task (as listed)Description (as listed)EnvironmentSkill levelCapture setupStatus
Pack a lunchboxPack a lunchbox with items into compartments.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request
Slice + spreadSlice bread and spread a condiment.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request
Crack + whisk eggsCrack eggs and whisk, then pour to pan.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request
Stir + flip on stovetopStir a pan and flip contents.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request
Knead + roll doughKnead dough and roll it flat.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request
Measure + mixMeasure ingredients and mix a batter.Working Kitchen Set (food prep)MediumMultiview rig + handheld grippersAvailable on request

Compared with neighbouring pages

How does this page differ from packing and kitting, sandwich and salad assembly, meal plating and baking pages?

Each row summarizes what the named page covers, as stated on this site. Where a page does not name the lunchbox row, the table says so.
PageMain topicRows or tasks it namesLunchbox row on that page
This page: egocentric lunchbox packing dataPacking a lunchbox with items into compartments"Pack a lunchbox" (Medium, Available on request)The main topic
Egocentric packing and kitting dataCartons, bagging, wrapping, sealing, labeling and kit building at pack benches and kitting stationsA broad family of packing rowsOne row among containers and mailers; not that page’s subject
Egocentric sandwich and salad assembly dataAssembling food by handA salad row (Medium) and an order assembly row for burgers, wraps and sides (Easy)Named as a neighbouring row only; not stated as a sandwich or a bowl
Egocentric meal plating and serving dataPlating dishes, portioning food and serving to a guest or tablePlating, portioning and serving rows, as the catalog lists themNot that page’s subject
Egocentric baking and dough handling dataKneading dough, rolling it flat, measuring and mixing a batter"Knead + roll dough" and "Measure + mix"A neighbouring row in the same Working Kitchen Set

Where lunchbox packing is named

Where does the site name lunchbox packing, and in what words?

Each statement is quoted or closely paraphrased from a page on this site. Several rows record what is not stated.
WhereWording on the siteWhat it tells you
Commercial task catalog: Working Kitchen Set"Pack a lunchbox": "Pack a lunchbox with items into compartments."One medium row, available on request; no item or box type named
Egocentric packing and kitting pageSmaller-scale packing in retail, food and office settings includes packing a lunchbox into compartmentsLunchbox packing appears there as one row in a broad family
Egocentric sandwich and salad assembly pageNeighbouring rows "Slice + spread" and "Pack a lunchbox"; neither is stated as a sandwich or a bowlWhy a separate page exists for this row
Closing, sealing, labeling, unpacking or carrying a lunchbox; packing it into a bag or cartonNot stated as tasksSettled in a Spec Pilot; not claimed here
Items, box type, compartment count, brand, kitchen or facilityNot statedSettled in the skill spec; not claimed here

Streams and labels

Which streams and labels are delivered for lunchbox packing, and which are not stated?

Delivered items are stated elsewhere on this site. Items marked not stated are not promised on this page.
Stream or labelWhat it gives a packing episodeStatus
Head and wrist camerasFirst-person view of the task plus a closer view of the handsDelivered
Depth with confidence mapsBox and counter geometry, with a confidence map to mask low-confidence regionsDelivered
6-DoF IMU at 200 HzHead and wrist motion aligned to the video frameDelivered
3D hand and body pose, with per-joint visibility flags for the handsBoth hands across the step; occluded fingers flaggedDelivered
Contact eventsThe moment the hand meets an itemDelivered
Action segments (start_ns, end_ns, verb, noun)One labeled span per stepDelivered
One task instruction per episodeThe only language data the site ties to captureDelivered
Per-frame instance masks (848×480)Masks where the spec calls for themDelivered where specified
Consent artefact IDs and anonymization recordProvenance per episodeDelivered
Item type, compartment or fill stateNot listedNot stated
Task-completion scoreNot listedNot stated
Contact force or tactile readingsNot among the listed streamsNot stated
Food-safety, hygiene or certification claimNot among the listed streamsNot stated
Robot or teleoperation dataHuman first-person demonstrations onlyNot captured
Counts of contributors, hours and itemsSet per program in the skill specNot stated

Delivery formats

Which delivery formats are offered for a lunchbox packing dataset?

The formats the site lists for delivery, each with its official reference. A format is chosen per program.
FormatWhat it isOfficial reference
RLDSEpisode format for reinforcement-learning datasetsgithub.com/google-research/rlds
LeRobotDataset format and tooling from Hugging Facegithub.com/huggingface/lerobot
WebDatasetTar-shard format for streaming training datagithub.com/webdataset/webdataset
HDF5Hierarchical array formathdfgroup.org/solutions/hdf5
ZarrChunked array formatzarr.dev
Rerun .rrdRecording format for the Rerun viewerrerun.io/docs
Raw streams with metadataPer-stream files plus metadata; readable converter source ships alongsideNot a third-party format

Scoping checklist

What does a lunchbox request put into each part of a skill spec?

The parts of a skill spec as the site’s guide describes them, applied to a lunchbox request. The catalog wording is quoted where it helps; your own fields and numbers are agreed with you.
Skill-spec partWhat to name for a lunchbox requestDrawn from what the site states
Named skillThe verb and the noun: pack an item into a compartment, not "packing"Catalog wording "Pack a lunchbox with items into compartments."
Geometry that must be visibleWhat must be in frame and for how long: both hands, the item, the box and its compartmentsSet in the skill spec
Condition budget in hoursHours per condition cell, including items, boxes, people, settings and failure casesSet per program in the skill spec
Reject ruleThe conditions that fail an item, written firstObject out of frame for more than 15 percent of the episode; more than 35 percent invalid depth pixels in the manipulation region; an undocumented bystander
Acceptance testOne test that decides whether an attempt counts as completeYour acceptance test is agreed in the spec
Setting and capture tierThe Working Kitchen Set and a multiview rig with handheld grippers, or another tier you agreeThe catalog lists a capture setup per row
Episode boundaryOne item, one compartment, one full box or a longer runSet in the skill spec; the site does not state an episode length
Participants and lightingHandedness, technique and pace; daylight or low light; whether anyone else is in the sceneSet per program in the skill spec

Example footage

What does first-person capture look like on this site?

One real clip already published on this site, shown as a format and rig example: ten seconds of first-person home cooking with faces blurred. It does not show a lunchbox, packing or the Working Kitchen Set.

egocentric_cooking_10s.mp4 · first-person view · faces blurred · 1080 × 1080 web preview · format example, not a lunchbox clip

No lunchbox clip is published on the site, so this is labelled as a format example. Request a sample to see delivered files. See sample data outputs, request an egocentric data sample.

FAQ

Egocentric lunchbox packing data, answered.

What is egocentric lunchbox packing data?
Custom first-person video of people packing a lunchbox with items into compartments, captured by paid, consented contributors doing the task in a written skill spec, with synchronized streams, hand pose, contact events and action segments.
Does Firsthand capture lunchbox packing?
The task catalog lists "Pack a lunchbox" ("Pack a lunchbox with items into compartments.") as a medium row in the Working Kitchen Set (food prep), captured with a multiview rig and handheld grippers and Available on request. The site states no delivered hours of it, so it is collected on demand.
Is lunchbox packing captured with a head-mounted rig or a multiview rig?
The catalog lists a multiview rig with handheld grippers for this row. The head-mounted stereo rig is the site’s general instrumented tier. Which setup applies to your program is settled in the skill spec, and this page does not equate the two.
How is this different from packing and kitting data?
Egocentric packing and kitting data covers cartons, bagging, sealing and kits, and lists the lunchbox row as one row among containers and mailers. This page is about that single row: items set into the compartments of one box.
What streams and labels come with a lunchbox episode?
Ten hardware-synchronized streams, including head and wrist cameras, depth with confidence maps, IMU, 3D hand and body pose and instance segmentation, plus action segments with start_ns, end_ns, verb and noun, contact events and one task instruction per episode. There is no stated item-type, compartment or fill-state label.
How fast can a custom lunchbox packing dataset be collected?
From signed spec to first validated batch, a median of 48 hours where coverage is deep and three to four weeks where it is thin. The site does not say which timeline applies to the Working Kitchen Set, so ask when you request the quote.
Is the footage anonymized and consented?
Every contributor signs a written release, and each episode links to it by consent artefact ID. Faces, plates and screens are blurred irreversibly, speech is scrubbed of names, addresses and card numbers, and footage that cannot be de-identified is discarded.
Which formats are delivered, and who owns the data?
RLDS, LeRobot, WebDataset, HDF5, zarr or Rerun .rrd, or raw streams with metadata. The license is perpetual, irrevocable and worldwide, buyer-owned and non-exclusive by default, with exclusivity available as a separate term.
Sources

Where are these capture claims documented?

Request a custom lunchbox packing dataset.

Tell us the placements, the setting and the variation your model needs to see. We will quote reach, timeline and price against a written spec, with a first validated batch in a median of 48 hours where coverage is deep.