Pretraining data

Pretraining Data for Industrial and Warehouse Robots

An industrial or warehouse robot foundation model needs to generalize across sites, stations, and tools it has never seen, which means its pretraining corpus has to span far more facilities, work cells, and workers than any single fine-tuning task requires. We collect that egocentric pretraining data on demand, to a written spec, aligned across synchronized streams, and licensed for commercial training.
Streams
Ten, synced under 2 ms
First batch
Median 48 h
Billing
Per validated hour
License
Buyer-owned
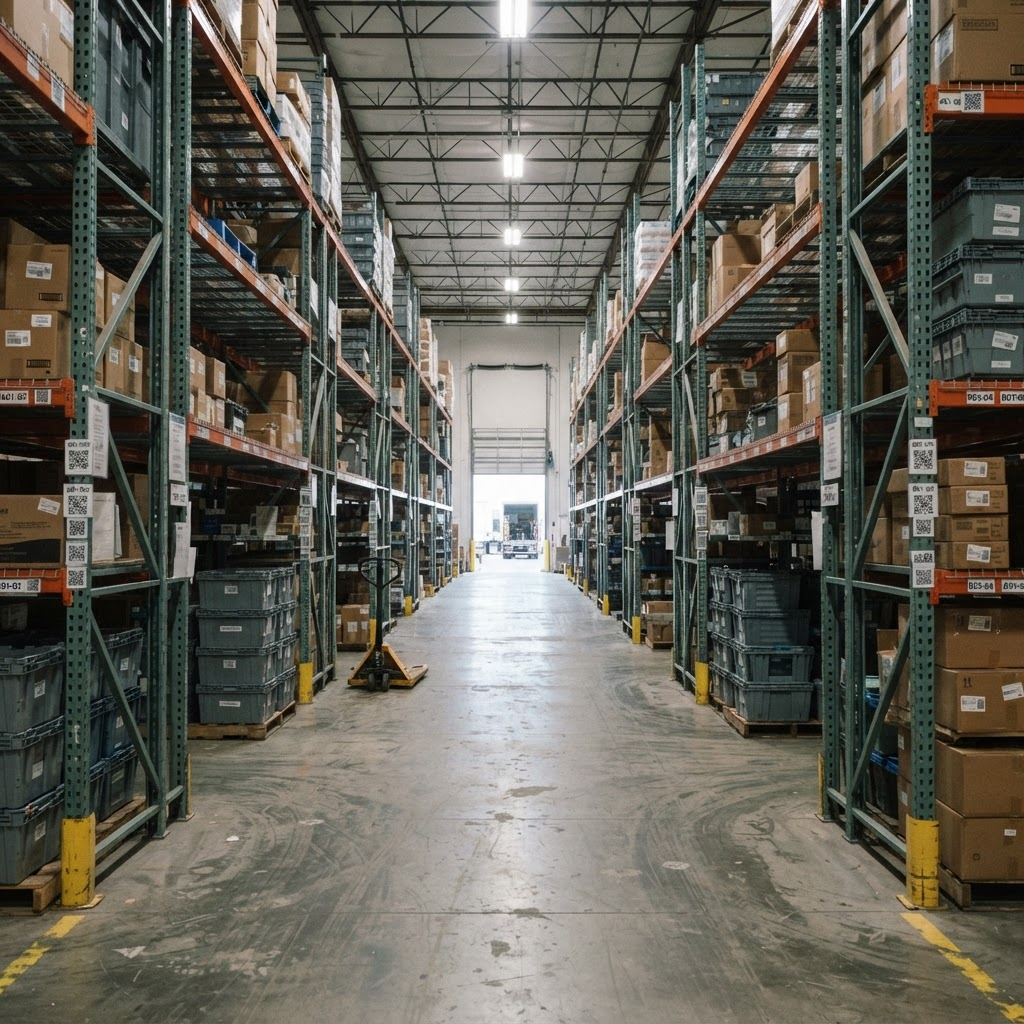
A warehouse pick aisle with steel racking, cartons and plastic totes, captured from a first-person viewpoint.
Industrial pretraining data has to span many sites and stations, not one recorded facility, to give a foundation model a general prior it can act on across a fleet.

Requirements

What does industrial pretraining data need that a single fine-tuning batch does not?

01

Scale across sites, not one recorded facility

An industrial foundation model has to generalize to sites it never captured data in, so the pretraining corpus needs to span many distinct facilities, work cells, and tool layouts rather than repeat one pick aisle or one workbench in depth.

02

Coverage across both warehouse and workshop task families

A fleet operating across logistics and manufacturing needs pretraining data that spans pick-and-pack cycles and bench assembly cycles alike, not one task family captured in isolation from the other.

03

Hand-level and depth-at-range detail together

A pick aisle needs depth that holds across long sight-lines; a bench needs 3D hand pose precise enough to resolve fastening and press-fit work. Industrial pretraining data needs both captured to their own known limits, not one stream standing in for the other.

04

Rights that clear a commercial run, captured on real sites

Industrial capture happens inside live, working facilities, which raises consent and safety requirements above a controlled studio capture, on top of the licensing terms a commercial pretraining program requires.

Definition

What is industrial robot pretraining data?

Industrial and warehouse robot pretraining data sits at the same base layer NVIDIA’s GR00T N1 describes in its data pyramid: web data and human video at the base because they are the most abundant, synthetic data in the middle, and real robot trajectories at the top because they are scarcest and most expensive to collect. For an industrial or warehouse robot, that base layer is egocentric human video of pick-and-pack, fastening, measuring, and pallet-build tasks, captured from a viewpoint close to what a robot’s onboard camera would see on a factory floor or in a fulfilment aisle.

That framing is why industrial pretraining leans on human capture rather than robot teleoperation logged inside live facilities: a person wearing a capture rig can move through far more sites and tasks per hour than a teleoperated robot arm can, and avoids the safety and access problems of running an early-stage robot through a working pick aisle or press-fit bench before it is ready.

Why pretraining scale

Why do industrial and warehouse robots need pretraining-scale data, not just fine-tuning data on one site?

An industrial robot deployed across a fleet will operate inside sites it never saw during training — different racking layouts, different tool sets, different part geometries, different workers. A model fine-tuned on one facility learns that facility; it does not learn to generalize to the next one. Pretraining-scale data is what gives the model a broad enough prior over sites, tools, and tasks that fine-tuning on any single deployment facility becomes a narrowing step rather than the model’s entire education.

EgoScale documents the general shape of this recipe: broad human pretraining first, establishing a log-linear scaling law between the amount of human pretraining data and validation loss, followed by a smaller, aligned mid-training stage matched to the target embodiment, and then task-specific fine-tuning. On a 22-degree-of-freedom dexterous hand, EgoScale reports a 54% average improvement in success rate over training with no human pretraining at all — evidence that the broad pretraining layer, not just the narrow fine-tuning stage, is doing real work. The same logic applies to an industrial robot: the pretraining corpus has to be broad across sites before any one deployment facility’s fine-tuning data can specialize effectively.

Generalist’s own framing from GEN-0 reinforces the same point in different words: "data quality and diversity matters more than sheer volume." An industrial pretraining corpus that repeats the same pick aisle or the same assembly bench a thousand times does not generalize any better than one that visits a hundred distinct sites once each — diversity of site, station, and tool is the variable that matters, not raw hour count alone.

Task and work-cell coverage

What tasks and work cells should an industrial pretraining set cover?

An industrial pretraining corpus needs the same named skill families already documented on this site for warehouse and assembly work — single-item pick, barcode scan, carton break-down, pallet stacking, and label application on the logistics side; fastening, measuring and marking to tolerance, press-fit assembly, and wire termination on the manufacturing side — but captured across many distinct sites and stations rather than concentrated in a small set of recorded facilities.

Coverage should span both work-cell families deliberately rather than defaulting to whichever is easier to schedule: pick aisle, pack bench, pallet build, and returns desk for warehouse work; home workshop, maker bench, and small production cell for assembly work. A fleet that operates across both needs pretraining data that reflects both, not one task family standing in for the other.

Streams and labels

What streams and labels should industrial pretraining data include?

The same ten-stream capture stack used across every Firsthand collection applies to industrial pretraining: 4K head camera, two wrist cameras, depth, IMU, 3D hand and body pose, instance segmentation, and action labels, hardware-aligned under 2 ms. Because video alone under-specifies what happened in a task, hand pose, contact events, and action segments turn raw floor footage into a signal a policy can actually learn a prior from.

Two known limits apply and are flagged rather than smoothed over. On the warehouse side, pick aisles have long sight-lines, and distance-invalid pixels beyond reliable depth range are flagged rather than interpolated. On the assembly side, small fasteners can fall below a depth sensor’s reliable floor, so metric depth on sub-centimetre parts is flagged the same way, while hand pose remains valid at that range. Knowing exactly where each stream stops being trustworthy is what makes the data usable for training rather than just watchable.

Human video vs robot data

Egocentric human video vs teleoperated robot data on the factory floor: which one scales?

Real robot trajectories sit at the top of the GR00T N1 data pyramid because they are the scarcest and most expensive tier to collect, and that is especially true inside live facilities: running a teleoperated robot through a working pick aisle or a press-fit bench raises safety and access constraints that a person wearing a capture rig does not face. Egocentric human video gives an industrial foundation model the same first-person viewpoint and physically grounded motion a robot will act from, at a fraction of the hardware cost and without needing a robot on hand at every site visited.

That is also why groups pursuing pretraining scale, like Generalist’s GEN-0 program, describe accumulating hundreds of thousands of hours of real-world manipulation data and adding more than 10,000 new hours every week — a rate of coverage that is only realistic with human capture, not robot teleoperation logged one facility at a time. Robot data still has a role: EgoScale’s own mid-training stage pairs roughly 50 hours of human video with about 4 hours of robot data across 344 tabletop tasks, a small, closely aligned dataset that comes after the broad human pretraining layer, not instead of it. The same ratio applies to an industrial program — broad human pretraining across many sites, then a smaller, closely aligned robot mid-training stage on the specific embodiment being deployed.

Diversity planning

How do you plan diversity across sites, tools, parts, and workers?

Diversity planning for an industrial pretraining corpus works the same way it does for any Firsthand collection: a written spec names the task list, the site and station types it needs to span, and the participant and lighting mix, rather than leaving coverage to whatever facility happens to be convenient. That spec should name the station types explicitly — pick aisle, pack bench, pallet build, and returns desk for logistics; home workshop, maker bench, and small production cell for manufacturing — since a fleet rarely operates in only one of these.

Tool and part diversity matters as much as site diversity. A corpus concentrated in facilities with similar racking, fastener types, and tool sets will generalize about as narrowly as one concentrated in a single facility. Spanning distinct sites — different layouts, tool sets, and lighting such as mixed sodium and daylight in a warehouse or bench lighting in a workshop — is what gives the pretraining layer a prior broad enough that a specific facility’s fine-tuning data becomes a narrowing step rather than the model’s entire education.

Worker diversity closes the loop: capturing the same tasks performed by different operators, at different paces and with different habits, keeps a model from overfitting to one person’s particular way of stacking a pallet or seating a fastener. None of the three — sites, tools, workers — substitutes for the other two.

Consent, privacy, and safety

How are consent, privacy, and site safety handled in workplace capture?

Industrial capture happens inside live, working facilities with multi-person traffic and real operating hazards, which raises the bar above what a controlled studio capture needs. Every custom collection ships under a documented consent chain, with each episode linked to a signed contributor release, and faces, plates, and screens are detected and irreversibly blurred at ingest, with a reviewer confirming the result before anything ships.

Capturing on shift rather than in a mock aisle or staged bench means working around genuine multi-person traffic and cabling routed under required PPE that shifts wrist extrinsics, with per-session recalibration to account for it — the same operating conditions already documented for warehouse and assembly capture on this site. The anonymization record is delivered with the data, giving the program a clear paper trail from consent through anonymization to the license terms governing commercial training.

Public vs custom

Public industrial datasets vs custom collection: what is the actual gap?

Public egocentric corpora referenced across pretraining research — EgoScale, GEN-0, EgoVerse, Egocentric-10K — are captured broadly across everyday human behavior, not scoped to industrial or warehouse task distributions, site types, or the depth-at-range and hand-pose-at-close-range detail an industrial program needs. Most also carry research-only or unstated licensing terms rather than a right to train a commercial product on them. Incidental logistics footage in public corpora is similarly unsynchronized across streams and carries no manipulation-grade hand pose, because it was never captured against a named skill list in the first place.

A custom industrial pretraining collection closes that gap by capturing to a written spec across the specific sites, stations, and tasks a model is missing, with hardware-synchronized streams throughout, under a license written for commercial training from the outset. A public dataset was captured for someone else’s task distribution, so it will always be missing exactly the site layouts or tool types a given industrial model needs next.

How it works

How does custom industrial pretraining collection work?

You describe the sites, stations, and tasks your pretraining corpus is missing. That becomes a written spec covering the task list, the site and station types it needs to span, the participant and lighting mix, capture tier, annotation depth, and accept criteria, quoted for reach, timeline, and price before any capture begins. Many programs start with a Spec Pilot, a small, fast first batch that proves the spec and accept criteria before scaling volume.

From there the collection runs through the same seven-stage end-to-end pipeline as every Firsthand program: contributor recruiting, capture across the specified sites, per-batch QA, anonymization, and licensed delivery, with rejected items recaptured at our cost and on-demand top-ups running against the same accept criteria afterward. A median 48-hour turnaround on a first batch means an industrial pretraining program can validate its spec — site coverage, tool diversity, depth and hand-pose quality — quickly, before scaling the same pipeline to the volume the fleet needs.

Delivery

What formats does industrial pretraining data ship in?

RLDS, LeRobot, and WebDataset, plus HDF5, zarr, and Rerun .rrd, so an industrial pretraining corpus loads directly into the same pipelines used for mid-training and fine-tuning data. Converter source is readable, so you can retarget the schema to your own loader.

Next step

How do you request an industrial or warehouse pretraining dataset?

Start with the site types, station types, or tasks your current industrial corpus is weakest on rather than a total hour target. That gap becomes the written spec — task list, sites and stations, participant and lighting mix, capture tier, annotation depth, and accept criteria — quoted for reach, timeline, and price up front.

A Spec Pilot proves that spec on a small, fast first batch before any commitment to scale, so you can check depth-at-range and hand-pose fidelity, and format compatibility with your training pipeline before volume ramps. From there, the same seven-stage pipeline scales the corpus to the size the fleet needs, with on-demand top-ups available afterward as new gaps in site or station coverage show up during training.

Task coverage

What industrial and warehouse task categories should a pretraining set cover, and what does each exercise?

Warehouse and assembly task categories and what each one exercises, as captured in the warehouse-picking and tool-use-assembly datasets on this site.
Task categoryWhat it exercises
Single-item pick from bin to toteObject recognition amid dense racking
Barcode scan with a handheld gunHand-eye coordination, fine manipulation
Carton break-down and pallet stackingLong-horizon sequencing, whole-body coordination
Driver and bit selection, drive to seatHand-level tool use precision
Clamp, align, and fasten a jointBimanual coordination, contact events
Press-fit and interference assembly, wire terminationFine manipulation below typical depth-sensor resolution

Every collection runs through the same seven-stage end-to-end custom collection pipeline.

Reported scale

Public pretraining corpora vs a custom industrial collection

Reported scale, capture setup, and licensing for named public pretraining corpora compared with a custom Firsthand industrial collection.
CorpusHours (as reported)Capture setupLicense
EgoScale20,854 hours, action-labeled egocentric human videoLabels from off-the-shelf SLAM and hand-pose estimationNot stated in the paper
GEN-0 (Generalist)270,000+ hours; 10,000+ new hours per weekReal-world manipulation data at scaleNot published
EgoVerseRoughly 1,362 hours across ~80,000 episodesEgocentric video corpusNot stated in the paper
Egocentric-10K10,000 hoursEgocentric video corpusApache 2.0
Custom Firsthand industrial collectionScoped to your written spec, no fixed corpus sizeEgocentric, hardware-synced, ten streams; depth-at-range and hand-pose detail flagged to known limitsPerpetual, buyer-owned, commercial

Reference datasets

How do the warehouse-picking and tool-use-assembly datasets on this site illustrate industrial-scale capture?

Documented scale and coverage of the warehouse-picking and tool-use-assembly datasets already shipping on this site, as a reference point for industrial pretraining scope.
AttributeWarehouse-picking datasetTool-use-assembly dataset
Validated hours1,420 hours1,680 hours
Episodes9,06011,240
Participants138152
Capture sites2244
EnvironmentsPick aisle, pack bench, pallet build, returns deskHome workshop, maker bench, small production cell

FAQ

Industrial robot pretraining data, answered.

What is industrial robot pretraining data?
It is large-scale, general-purpose egocentric capture of factory, workshop, and warehouse tasks — pick and pack, fastening, measuring, and pallet-build — used to train the general base layer of an industrial or warehouse robot foundation model before it is aligned to any one site, station, or robot.
How is industrial pretraining data different from the warehouse-picking or tool-use-assembly datasets?
The warehouse-picking and tool-use-assembly datasets are fixed, shipping corpora of 1,420 and 1,680 validated hours respectively. Industrial pretraining data is a custom collection scoped by written spec to the specific sites, stations, and tasks your model is missing, with no fixed corpus size.
Why does industrial pretraining need both depth-at-range and hand-pose-at-close-range detail?
A pick aisle needs depth that holds across long sight-lines, while a bench needs 3D hand pose precise enough to resolve fastening and press-fit work below a typical depth sensor’s reliable floor. Each stream is flagged rather than interpolated where it stops being trustworthy, so both task families are usable for training.
Should industrial pretraining data use egocentric human video or robot data?
Egocentric human video is the pretraining-scale layer, giving the same first-person viewpoint a robot will act from without needing a robot on hand at every site. Robot data plays a smaller, aligned mid-training role afterward, as in EgoScale’s roughly 50-hour human plus 4-hour robot mid-training stage.
What sites and stations does an industrial pretraining spec need to cover?
Pick aisle, pack bench, pallet build, and returns desk on the logistics side, plus home workshop, maker bench, and small production cell on the manufacturing side, since a fleet rarely operates in only one of these station types.
How is safety handled when capturing on a live factory floor or in a working warehouse?
Capture happens on shift rather than in a mock aisle or staged bench, with per-session recalibration to account for cabling routed under required PPE and genuine multi-person traffic, plus the same documented consent chain and anonymization pipeline used across every Firsthand collection.
Can industrial pretraining data be combined with the warehouse-picking or tool-use-assembly datasets?
Yes. Those fixed datasets offer a reference corpus, while a custom industrial pretraining collection fills specific gaps in site, tool, or station diversity that a fixed dataset cannot cover on demand.
How do you request a custom industrial or warehouse pretraining dataset?
Describe the sites, stations, and tasks your corpus is missing. That becomes a written spec quoted for reach, timeline, and price, typically starting with a Spec Pilot before scaling to full volume.
Sources

Where are these industrial pretraining claims documented?

Request a custom industrial pretraining dataset.

Tell us the sites, stations, and tasks your industrial foundation model needs to see. We will quote reach, timeline, and price against a written spec, with a first validated batch in a median of 48 hours.