Same viewpoint, three names
POV, first-person, and egocentric video all mean a camera worn or held at the actor’s own eye line, capturing what the actor sees rather than how they look from outside.
POV video
What is included
POV, first-person, and egocentric video all mean a camera worn or held at the actor’s own eye line, capturing what the actor sees rather than how they look from outside.
A phone in a chest mount for breadth, a head-mounted rig when gaze and head motion matter, or a synchronized multi-camera rig when a model needs 3D hand pose and contacts.
Each batch is reviewed against written accept criteria, rejected items are recaptured at the provider’s cost, and faces, plates, and screens are blurred and reviewer-confirmed before delivery.
RLDS, LeRobot, WebDataset, HDF5, zarr, or Rerun .rrd, under a perpetual, buyer-owned commercial license.
Terminology
POV video data is video recorded from the point of view of the person performing a task. The camera sits where the actor’s eyes would be, mounted on the head, the chest, or a pair of glasses, so every frame shows hands, tools, and objects the way the actor sees them rather than showing the actor’s body from across the room. "POV" is shorthand for point of view, and a point-of-view video dataset is a collection of those recordings assembled against a written spec instead of gathered from whatever happens to exist online.
That viewpoint matters for AI and robot training because a policy learning to manipulate objects needs to see the task the way a hand-eye system experiences it, not the way a bystander would film it. A third-person clip shows what a person looks like doing a task; a POV clip shows what the task looks like from inside the doing of it. Grasp points, tool contact, and the changes in viewpoint as the actor reaches, turns, or leans in are all visible in the frame because the camera moves with the actor.
Terminology
Yes. "POV video," "first-person video," and "egocentric video" describe the same capture viewpoint: a camera worn or held at the actor’s own eye line. The terms come from different communities. "Egocentric" is the term used in the computer vision and robotics research literature, "POV" is common in consumer and creator contexts, and "first-person" is the plain-language version buyers use when they describe what they need without the research jargon.
Because the capture method, contributor recruiting, hardware tiers, annotation, and delivery are identical regardless of which term a buyer searches, a custom POV video collection and a custom egocentric video collection are the same offer under different names. The practical difference is in what the search term usually brings with it. A creator’s POV clip is typically an edited video shot for an audience. A POV training dataset is footage captured for a model, to a spec, with the consent, anonymization, and license a model builder needs.
Scope
A custom POV video collection starts with a written spec and ends with licensed, training-ready delivery. In between it covers contributor recruiting and briefing, capture against the spec, per-batch quality review, anonymization, documented consent, and delivery in the format your pipeline already loads. Contributors are paid hourly, and billing is per validated hour, meaning footage that actually passed sync and QA against the spec, not per raw hour recorded.
Most programs start with a Spec Pilot, a small, fast first batch that proves the spec and the QA bar on real footage before volume scales. The spec is quoted for reach, timeline, and price before capture begins, so the buyer sees the terms of the engagement up front. From there the same pipeline scales the collection to the size the program needs, and on-demand top-ups run against the same accept criteria afterward, so new gaps that appear during training can be closed without renegotiating the spec from zero.
Capture
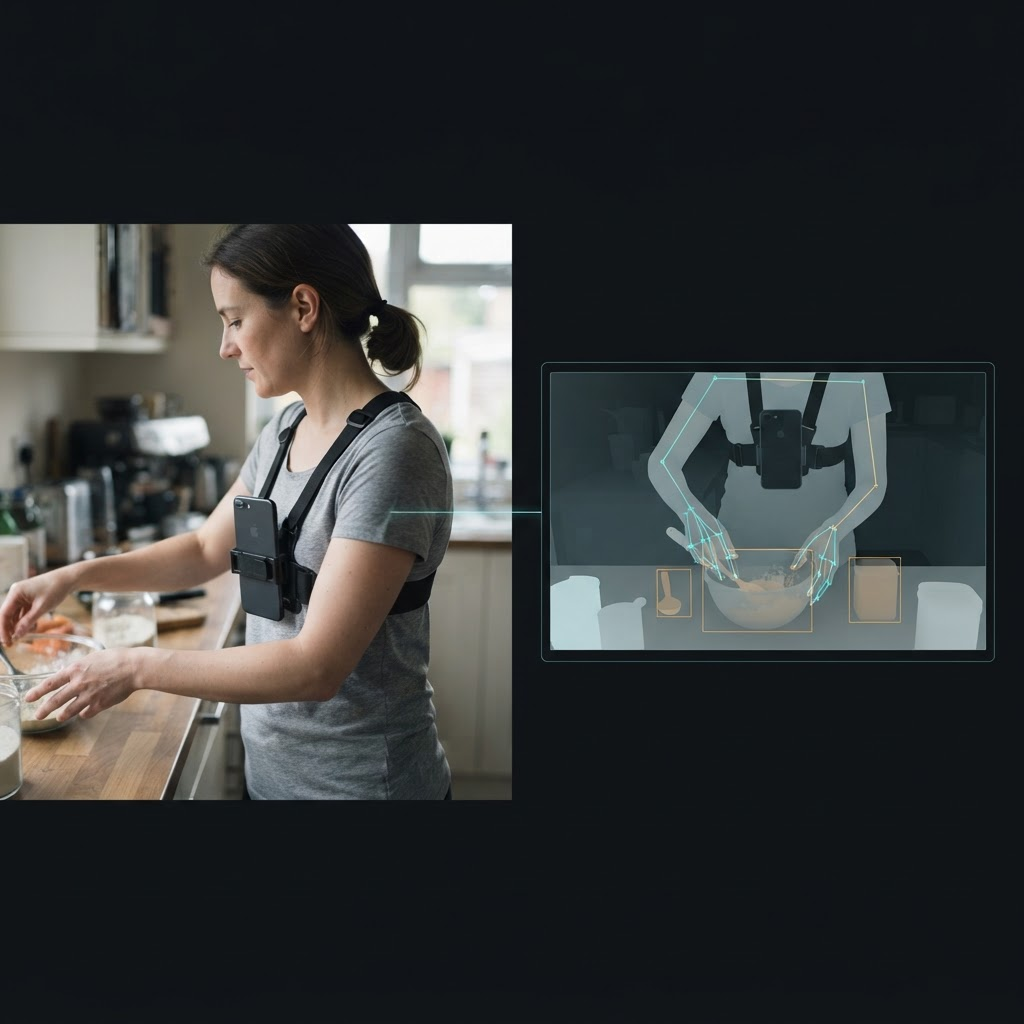
Capture runs on one of three tiers, and programs often mix tiers under one spec. The phone tier is a contributor filming hands-free with a phone in a chest mount, which is the fastest way to reach broad geographic and household diversity. The head-rig tier uses a head-mounted camera that matches the eye-line viewpoint and adds IMU data, for tasks where gaze and head motion are part of what the model needs to learn. The multi-camera tier synchronizes head, wrist, and depth streams on one hardware clock, for manipulation work that needs 3D hand pose and contacts.
The instrumented rig behind the multi-camera tier carries a Sony IMX585 global-shutter head camera with a 120° field-of-view lens, two IMX290 wrist cameras with a 100° lens each, an Intel RealSense D435if depth sensor mounted on the forehead, and three Bosch BMI088 inertial measurement units running at 200 Hz, one on the head and one on each wrist. A PTP grandmaster clock and hardware trigger line drive every sensor off the same timebase, with a 2.0 millisecond sync ceiling. The head camera is a 4K/60 global-shutter camera.
There is also a lighter head-mounted option: a contributor-worn dual-lens 360 camera clipped to a quick-release buckle on an elastic head strap. It gives up depth, wrist views, and sub-millisecond sync, and in exchange it goes anywhere a person is willing to wear it, which is how coverage reaches a wide range of countries and households. Episode metadata labels which tier a clip came from, so a buyer can filter on tier rather than infer it.
Streams and labels
Which streams ship depends on the tier. Phone-tier footage is first-person RGB video. Head-rig captures add IMU. Multi-camera captures add wrist video and depth, all on one hardware clock so the streams line up to the frame. Not every order needs every stream: depth, IMU, and hand pose are added where the spec calls for them.
Labels are annotations rather than sensors. They are produced from the captured streams and carry timestamps aligned to every other stream. Hand pose is delivered at 21 joints per hand in metric 3D, with a per-joint visibility flag. Action segments divide a task into start- and end-timestamped spans, each carrying start_ns, end_ns, verb, and noun. Annotation options on this site also include objects and transcripts, and contact events are available for hand-object contact work.
Delivery
POV data ships in RLDS, LeRobot, WebDataset, HDF5, zarr, or Rerun .rrd, and as MP4 plus JSONL. The aim is to match whatever format the buyer’s training pipeline already loads instead of asking the pipeline to change. RLDS is an open-source robot-learning dataset format, LeRobot is Hugging Face’s robot-learning dataset format, WebDataset is a tar-shard format, and HDF5 is the container behind the HDF5 and zarr exports. Each links to its official source in the Sources section below.
For multiview episodes the stream names differ by format, and the formats table shows the key for the head RGB stream. In the HDF5 and zarr export the streams appear as separate streams under one group, each with its own nanosecond timestamp. Head RGB is full 4K, so decode it lazily or downscale it in the input pipeline.
Speed
A median of 48 hours from signed spec to first validated batch applies where coverage is deep, meaning contributors already exist for the tasks and places the spec names. Where coverage is thin and contributors have to be recruited from scratch, a realistic timeline runs three to four weeks. The site publishes no faster figure than those two.
Both numbers measure the time to the first validated batch, which is a batch that has cleared the accept criteria written into the spec. Batches that fail are rejected and recaptured at the provider’s cost rather than shipped with a caveat, so a first batch is validated footage, not a rough cut. The site states no time to a full-size dataset. After the pilot, on-demand top-ups run against the same accept criteria as new gaps appear.
Rights
Every contributor signs a documented release as part of the consent chain, and that record ships with the data instead of being kept as a one-time assurance behind the scenes. POV footage is captured in real environments from the actor’s own viewpoint, so it can pick up bystanders, license plates, and screens in frame. Those are detected and irreversibly blurred at ingest, and a human reviewer confirms the anonymization before anything ships, with the anonymization record delivered alongside the data.
The finished dataset is delivered under a perpetual, buyer-owned commercial license. The grant is irrevocable, worldwide, and non-exclusive by default, and exclusivity is available so a given collection is never resold to another buyer. That combination, a documented consent chain plus a license written for commercial training from the start, is where several public first-person or egocentric corpora fall short, since many ship research-only terms or do not state a license at all.
Comparison
Third-person footage shows the actor from outside: a camera across the room, or a creator’s clip shot for an audience rather than for a model. It does not show the hand-object geometry, grasp points, or viewpoint changes a manipulation policy needs, because the camera was never placed where the actor’s eyes or hands were during the task. POV capture puts the camera at the actor’s viewpoint on purpose, so the frames show grasps, tool contact, and task-relevant motion the way an embodied system encounters them.
That is why egocentric or first-person data has become the standard capture viewpoint for pretraining and mid-training robot foundation models, ahead of internet-scraped or third-person footage. The table compares the three on viewpoint, hand-object geometry, task coverage, licensing, and consent, and a longer side-by-side is in the egocentric vs third-person comparison. This page states no measured benchmark gain for POV over third-person video; the comparison is about what each viewpoint can show and which rights come with it.
At a glance
| Stream or label | What it is for |
|---|---|
| First-person RGB video | The core training signal: hands, tools, and objects from the actor’s own viewpoint |
| IMU (head-rig and multi-camera tiers) | Head motion and orientation, at 200 Hz on the instrumented rig |
| Wrist video and depth (multi-camera tier) | A close view of the hand at contact, plus 3D geometry for hand pose and contacts |
| 21-joint 3D hand pose | 21 joints per hand in metric 3D, with a per-joint visibility flag |
| Action segments | Start- and end-timestamped spans carrying start_ns, end_ns, verb, and noun |
| Objects and transcripts | Labels for what is handled and what is said, for supervised training |
| Calibration record | Opening and closing solve per session, with drift written to episode metadata |
| Anonymization record | Documentation that faces, plates, and screens were detected, blurred, and reviewer-confirmed |
Every collection runs through the same seven-stage end-to-end custom collection pipeline.
Terminology
| Term | Where it is common | What it describes | Same capture on this site? |
|---|---|---|---|
| POV video | Consumer and creator contexts | A camera worn or held at the actor’s own eye line | Yes |
| First-person video | Buyers describing what they need in plain language | The same eye-line viewpoint | Yes |
| Egocentric video | Computer vision and robotics research literature | The same eye-line viewpoint | Yes |
| Head-mounted video | Capture-hardware descriptions | One mounting point: a camera fixed at head height, used when gaze and head motion matter most | Yes, as one way to collect POV video |
Capture setup
| Tier | Mount and camera | Streams | Best for |
|---|---|---|---|
| Phone | Phone in a chest mount, filmed hands-free | First-person RGB video | Breadth and household or geographic diversity |
| Head rig | Head-mounted camera at the eye-line viewpoint | First-person RGB video plus IMU | Tasks where gaze and head motion matter |
| Multi-camera | Instrumented head rig with wrist cameras and depth | Head, wrist, and depth video plus IMU on one hardware clock, 2.0 ms sync ceiling | Manipulation that needs 3D hand pose and contacts |
| 360 head strap | Contributor-worn dual-lens 360 camera on an elastic head strap | Single camera; no depth, wrist views, or cross-stream sync claim | Reach into more environments and countries |
Formats
| Format | What it is | Head RGB key in multiview episodes |
|---|---|---|
| RLDS | Open-source dataset format for robot learning | observation.head_rgb |
| LeRobot | Hugging Face’s robot-learning dataset format | observation.images.head |
| WebDataset | Tar-shard format | head.jpg |
| HDF5 and zarr | The container behind the HDF5 and zarr delivery formats; streams stored separately under one group | head_rgb |
| Rerun .rrd | Rerun recording delivery option | Not stated on this site |
| MP4 + JSONL | Video files with JSONL alongside | Not stated on this site |
Stated vs set per program
| Detail | What the site states | Set per program |
|---|---|---|
| Spec to first validated batch | A median of 48 hours where coverage is deep; three to four weeks where thin | Which of the two applies to your tasks and regions |
| Hours in a collection | Not stated; scope starts from the data gap, not an hour count | Quoted in the spec |
| Price | Not stated; quoted before capture and billed per validated hour | Quoted in the spec |
| Capture tier | Phone, head rig, or multi-camera; tiers can be mixed | Chosen in the spec |
| Annotation depth | Actions, hand pose, objects, transcripts | Chosen in the spec |
| Exclusivity | Non-exclusive by default; exclusivity available | Agreed with the license |
| Accept criteria | Written into the spec; failed batches recaptured at the provider’s cost | Written per program |
Viewpoint comparison
| POV video | Third-person video | Internet video | |
|---|---|---|---|
| Viewpoint | Actor’s own eye line; hands and tools as the actor sees them | External camera showing the actor’s body from outside | Whatever viewpoint the original creator filmed from |
| Hand-object geometry | Captured directly, matching how an embodied system encounters the task | Occluded or distant; not aligned to a model’s own viewpoint | Inconsistent; rarely aligned to any single viewpoint |
| Task coverage | Scoped to the written spec’s tasks and environments | Depends on what was filmed, not specified to a model’s gap | Whatever exists online; not controllable |
| Licensing | Perpetual, buyer-owned commercial license by default | Varies by source | Scraped video typically lacks commercial training rights |
| Consent documentation | Documented per-contributor consent chain delivered with the data | Varies | Usually absent |
FAQ
Sources
Tell us the tasks, environments, capture tier, and the format you load from. We write them into a spec and quote reach, timeline, and price before capture begins.